ai/qwen3.8-flash-next repository overview
Read our How to Run Qwen3.8-Flash-Next Guide!
Unsloth Dynamic 3.0 achieves superior accuracy & outperforms other leading quants.


- MTP is now available for 1.3-1.7x Faster inference in Unsloth. Read Guide
- To run, please use llama.cpp or use our Unsloth Desktop app.
- See below for Qwen3.8-Flash-Next run in Unsloth Desktop with thinking controls:

Qwen3.8-Flash-Next
As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next.
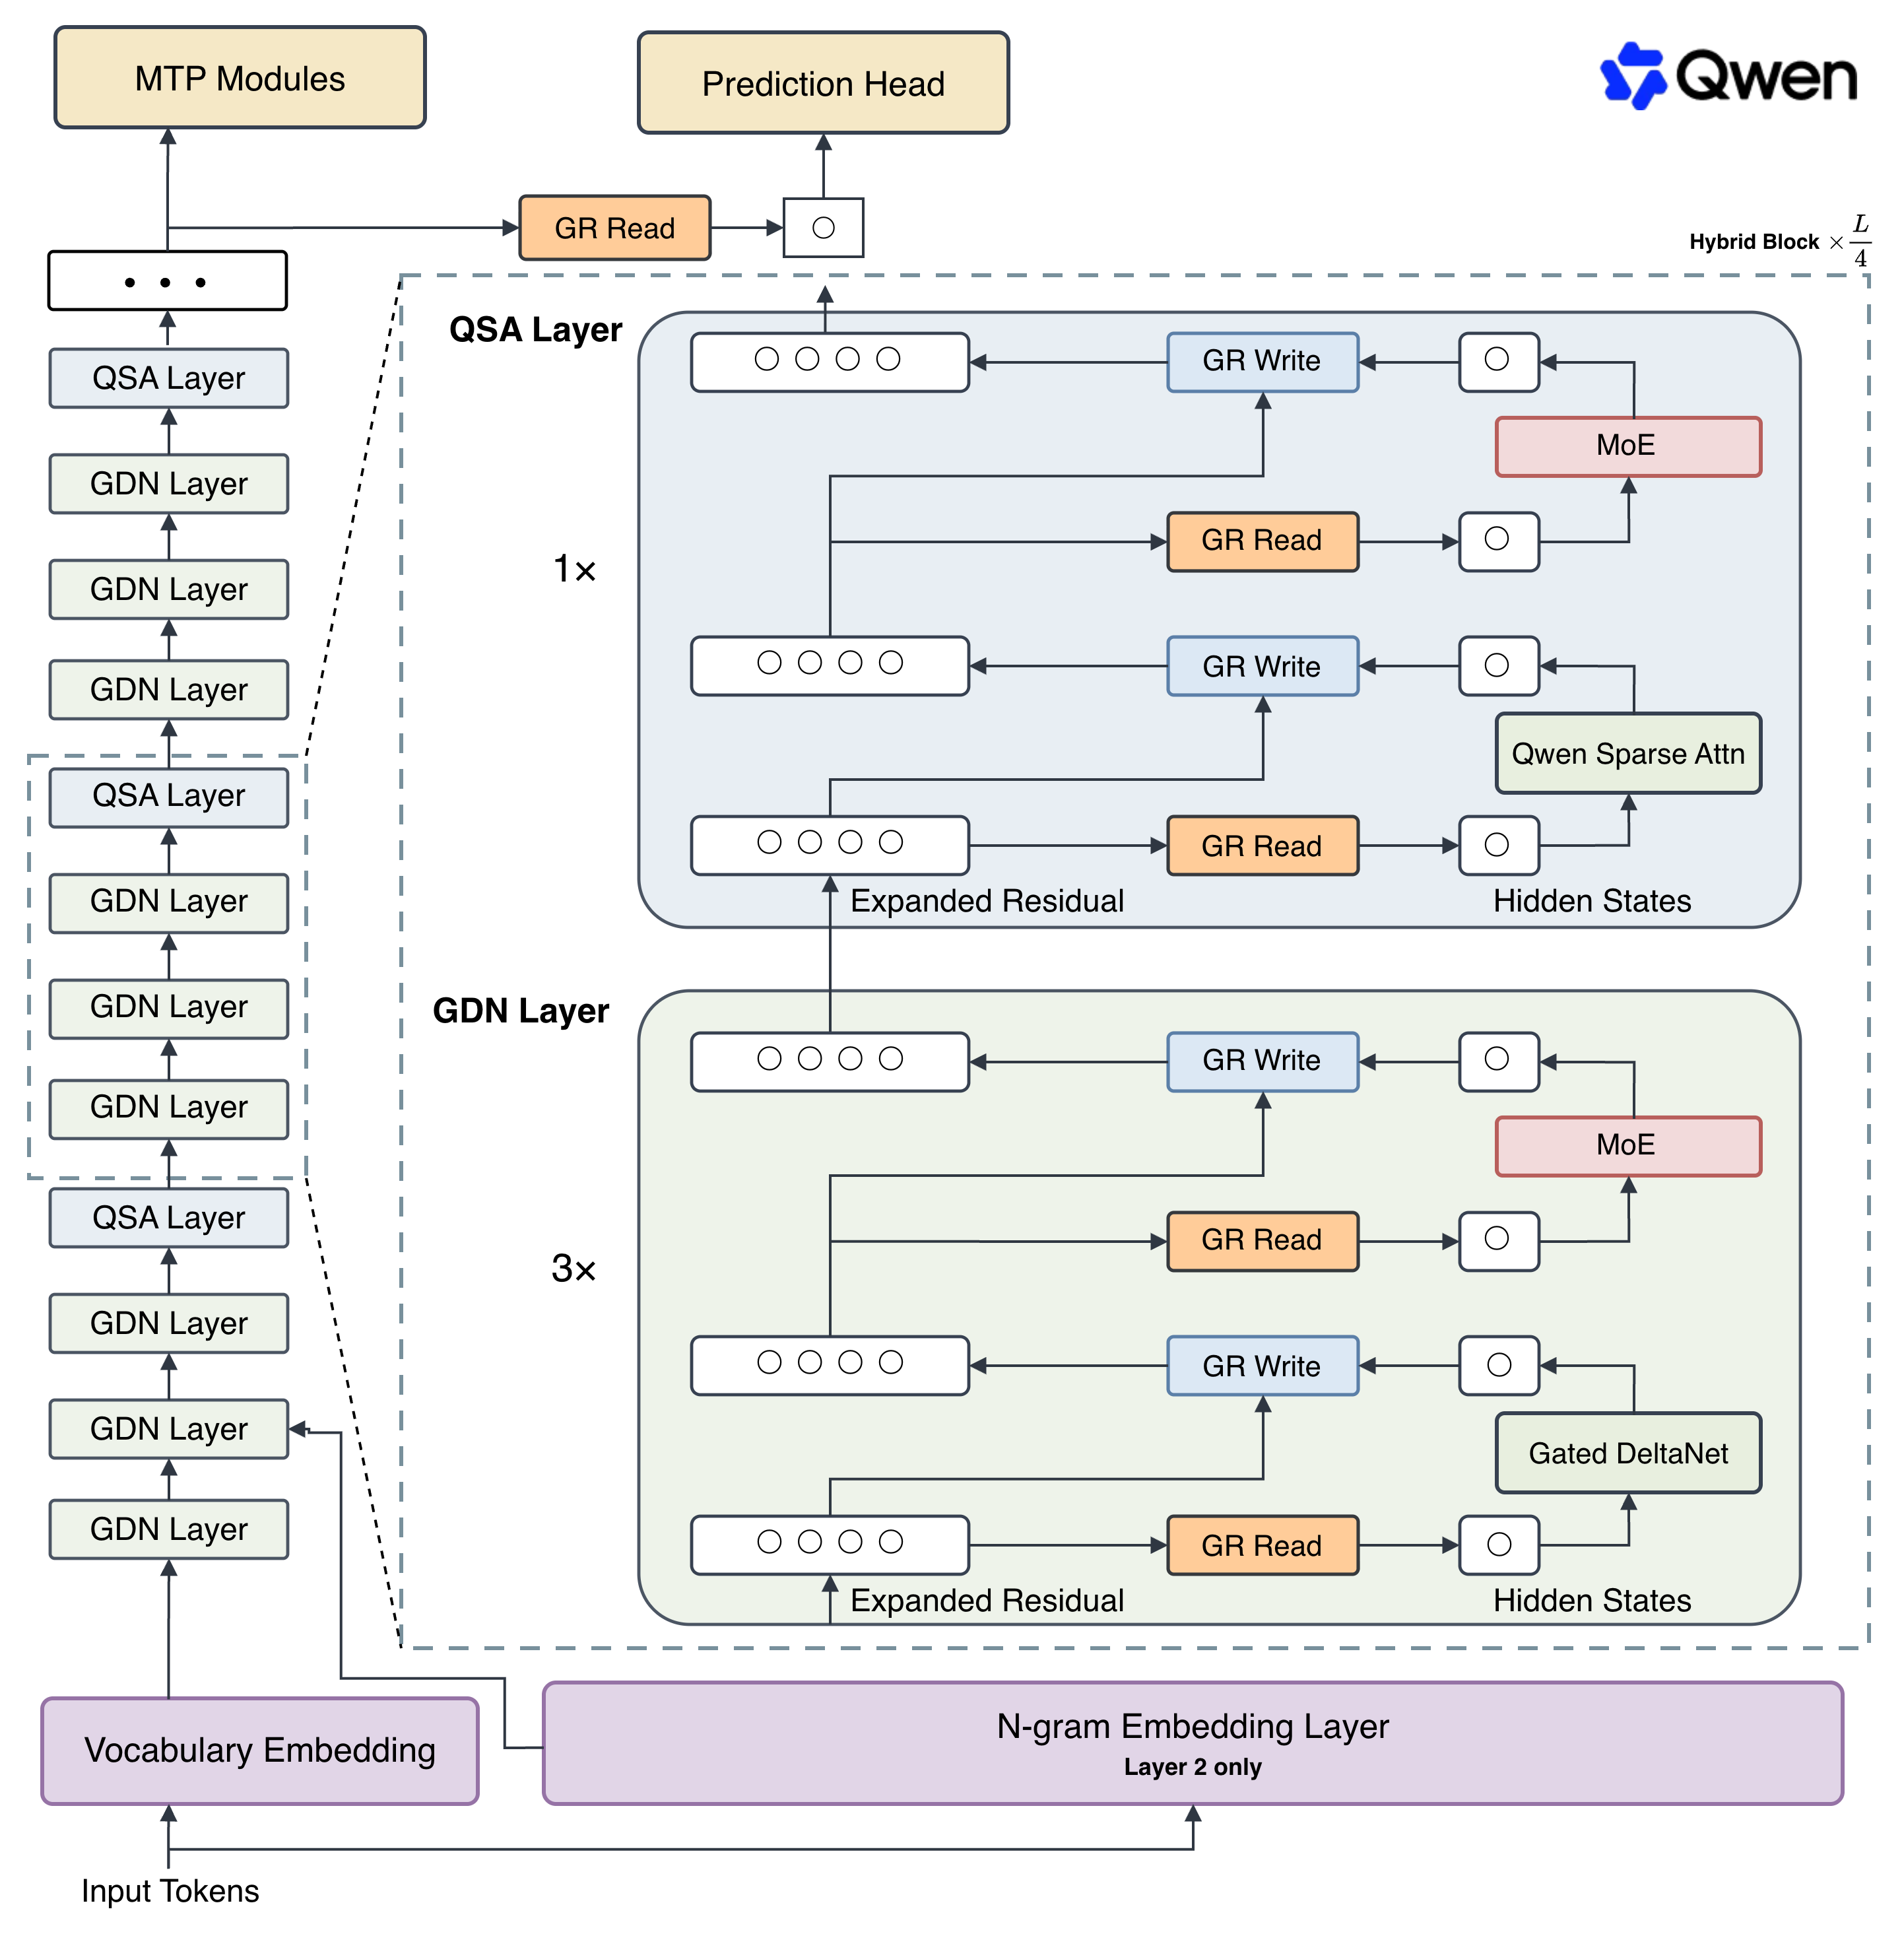
This experimental preview of the architecture that will underpin Qwen4 is built around a fundamental rethinking of how the core components of modern large language models (LLMs) interact at scale.
Highlights
The first open-weight release under this architecture is Qwen3.8-Flash-Next, which introduces:
- Hybrid Attention with QSA: The Gated DeltaNet and Gated Attention pairing has been reworked into Gated DeltaNet and Qwen Sparse Attention (QSA). Rather than selecting individual tokens for processing, QSA operates at the micro-block level. This cuts long-context latency significantly, a critical gain as agentic workloads increasingly dominate real-world usage.
- Gated Residual: Residual streams with normalization are what make deep LLM training manageable. Gated Residual modulates information flowing through widened residual streams via an element-wise, data-dependent read gate and a per-branch scalar write gate. This brings finer-grained expressiveness across layers while preserving training stability and keeping inference overhead low.
- N-gram Embedding: Embeddings provide a unique axis for parameter scaling that requires less computation and is more amenable to offloading than Mixture-of-Experts (MoE). By indexing with short n-grams, this approach makes parameter scaling highly efficient for memory-constrained accelerators without sacrificing quality.
- Tailored Training Recipe: The Muon and AdamW optimizers are applied to specific weight categories to maximize efficiency. Guided by refitted scaling laws, we eliminate traditional batch-size warmups and start directly at the target batch size, substantially reducing total optimizer steps while safely supporting larger learning rates for robust convergence.
For more details, please refer to our blog post Qwen3.8-Flash-Next and the technical report.
We are excited to embark on this next chapter with you and welcome your feedback as we build what comes next.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 125B with 6B activated, plus 51B n-gram embedding and 4B MTP
- Hidden Dimension: 2560
- Token Embedding: 248320 (Padded)
- N-gram Embedding: 20,000,000 (bigrams/trigrams at layer 2)
- Number of Layers: 48
- Hidden Layout: 12 × (3 × (Gated DeltaNet → MoE) → 1 × (Qwen Sparse Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Qwen Sparse Attention:
- Number of Attention Heads: 24 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Indexer Structure: MQA with 4 Query Heads and 1 Shared Key Head
- Indexer Head Dimension: 128
- Budget: 512 blocks or 2048 tokens
- Mixture Of Experts
- Number of Experts: 512
- Number of Activated Experts: 10 Routed + 1 Shared
- Expert Intermediate Dimension: 640
- Gated Residual:
- Number of Branches: 4
- Bottleneck Rank: 320
- LM Output: 248320 (Padded)
- MTP: 1 layer, trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,000,000 tokens.
Benchmark Results
.vl-table th{font-size:15px!important;line-height:1.2} .vl-table td:not(.benchmark-cell):not([colspan]){font-size:15px;line-height:1.2;vertical-align:middle} .vl-table .benchmark-cell{padding:12px 10px 12px 18px!important;vertical-align:middle} .vl-table .benchmark-capability{font-size:15px;font-weight:600;line-height:1.22;color:#171717} .vl-table .benchmark-name{margin-top:4px;font-size:11px;font-weight:400;line-height:1.2;color:#6B6B6B} .vl-table .metric-stack{display:flex;flex-direction:column;gap:7px;padding:3px 0} .vl-table .metric-label{font-size:10px;font-weight:400;line-height:1.1;color:#777} .vl-table .metric-value{margin-top:2px;font-size:15px;line-height:1.15;color:#171717} .vl-table .metric-pair{white-space:nowrap} .vl-table .metric-sep{color:#9A9A9A;padding:0 3px}Language
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | DeepSeek-V4-Flash-0731 | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|---|
# Params | 125B | 27B | 397B | 284B | -- |
# Activated params | 6B | 27B | 17B | 13B | -- |
# N-gram embedding params | 51B | -- | -- | -- | -- |
| Coding | |||||
Agentic coding DeepSWE 1.1 | 58.7 | 42.2 | 16.5 | 54.4 | -- |
Agentic coding SWE-bench Pro | 62.5 | 61.7 | 55.8 | 56.0 | 53.4 |
Multilingual software engineering SWE-bench Multilingual | 81.0 | 73.8 | 75.8 | -- | 77.5 |
Repo-level code generation NL2Repo-Bench | 48.1 | 42.3 | 41.1 | 54.2 | 47.6 |
| Agent | |||||
Long-horizon office work CoWorkBench | 73.9 | 70.7 | 65.1 | 45.1 | 68.2 |
Professional job tasks JobBench | 55.7 | 33.4 | 27.6 | 41.3 | 36.6 |
Frontier agentic tasks Agents' Last Exam | Pass@1 24.3 Score 51.2 | Pass@1 20.4 Score 42.9 | Pass@1 13.2 Score 33.6 | Pass@1 25.2 Score -- | -- |
Real-world tool use Toolathlon Verified (Pass@1) | 73.5 | 67.1 | 50.6 | 70.3 | -- |
| General | |||||
Instruction following IFB
…(truncated — see the full README on HuggingFace) |
Tag summary
Content type
Unrecognized
Digest
sha256:5d23f6859…
Size
104.5 GB
Last updated
20 days ago
docker pull ai/qwen3.8-flash-nextThis week's pulls
Pulls:
3,881
Last week