compagnonsdudev/kafkaexplorer
Explore Kafka, query it in Flink SQL, audit it with AI — one container, one URL.
5.1K
compagnonsdudev/kafkaexplorer repository overview
⚡ Kafka SQL Explorer
See your Kafka. Query it like a database. Audit it with AI.

Stop squinting at console consumers. Kafka SQL Explorer turns any Kafka cluster into something you can see and query: browse topics, click on a message field, and get a runnable Flink SQL query — no DDL to write, no schema to guess, no CLI gymnastics.
One container, one URL, zero cluster-side installation: it connects as an ordinary Kafka client, so there is nothing to deploy on your brokers.
🚀 Try it in one command
Against a broker you already have:
docker run --rm -p 127.0.0.1:8080:8080 \
  -e KAFKA_BOOTSTRAP_SERVERS=your-broker:9092 \
  compagnonsdudev/kafkaexplorer:latest
Open http://localhost:8080.
The port is published on the loopback interface deliberately — this image ships no authentication. See Before you expose it below.
No broker at hand? The snippet below starts Kafka 4.3 (KRaft, no Zookeeper) next to it:
# docker-compose.yml — throwaway sandbox, broker data is not persisted.
services:
  kafka:
    image: apache/kafka:4.3.1
    environment:
      KAFKA_NODE_ID: 1
      KAFKA_PROCESS_ROLES: broker,controller
      KAFKA_CONTROLLER_QUORUM_VOTERS: 1@kafka:9093
      KAFKA_LISTENERS: PLAINTEXT://:29092,CONTROLLER://:9093,PLAINTEXT_HOST://:9092
      KAFKA_ADVERTISED_LISTENERS: PLAINTEXT://kafka:29092,PLAINTEXT_HOST://localhost:9092
      KAFKA_LISTENER_SECURITY_PROTOCOL_MAP: CONTROLLER:PLAINTEXT,PLAINTEXT:PLAINTEXT,PLAINTEXT_HOST:PLAINTEXT
      KAFKA_CONTROLLER_LISTENER_NAMES: CONTROLLER
      KAFKA_INTER_BROKER_LISTENER_NAME: PLAINTEXT
      KAFKA_OFFSETS_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_TRANSACTION_STATE_LOG_REPLICATION_FACTOR: 1
      KAFKA_TRANSACTION_STATE_LOG_MIN_ISR: 1
      KAFKA_SHARE_COORDINATOR_STATE_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_SHARE_COORDINATOR_STATE_TOPIC_MIN_ISR: 1
      CLUSTER_ID: MkU2OhlMTT69sPFvS1n16g

  explorer:
    image: compagnonsdudev/kafkaexplorer:latest
    # No authentication in the box — see "Before you expose it" below.
    ports:
      - "127.0.0.1:8080:8080"
    # Not optional. The JVM runs with -XX:MaxRAMPercentage=75, which without a limit
    # reads the *host's* memory: on a 32 GB machine it believes it may take 24.
    mem_limit: 2g
    environment:
      KAFKA_BOOTSTRAP_SERVERS: kafka:29092
      KAFKA_CONSUMER_GROUP_PROTOCOL: consumer   # KIP-848, Kafka 4.x brokers only
    volumes:
      - explorer_logs:/app/logs
      - explorer_data:/app/data
    # Graceful web shutdown (15s) + bean destruction (10s) + JVM exit. Docker's default
    # of 10s SIGKILLs exactly what those budgets exist to protect.
    stop_grace_period: 35s
    depends_on: [kafka]

volumes:
  explorer_logs:
  explorer_data:
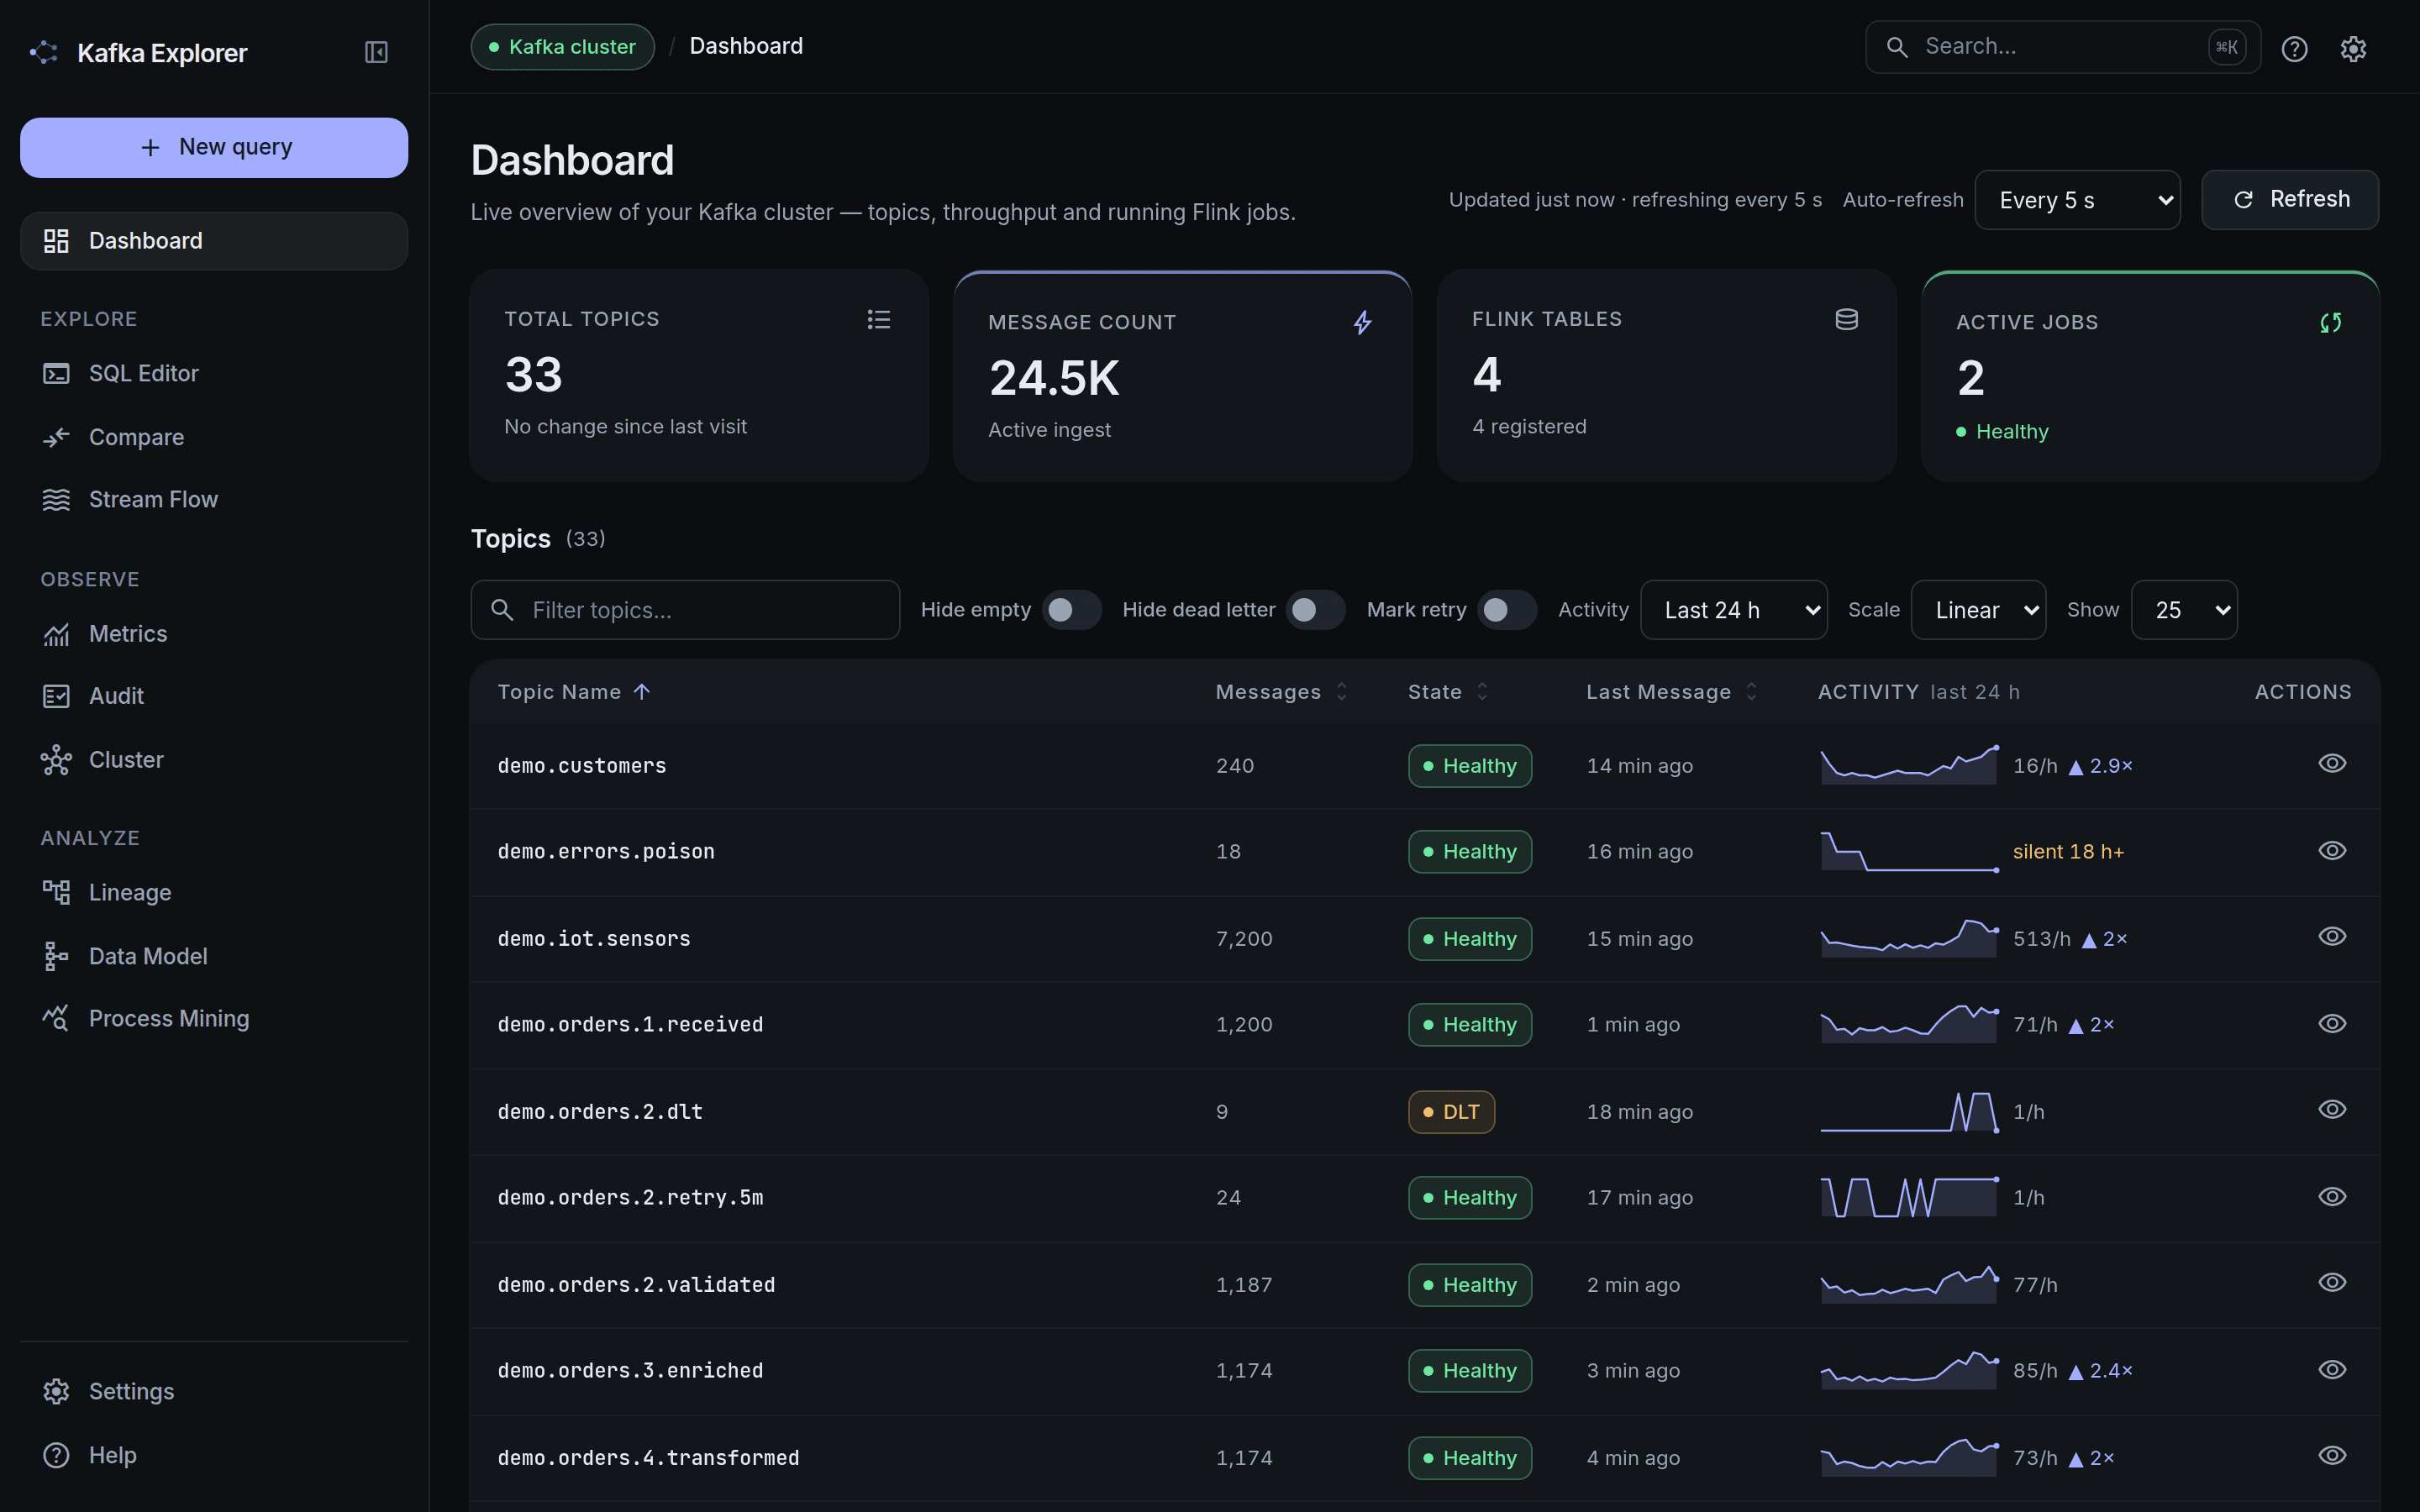
The repository's own stacks go
further: docker compose up -d there also seeds 76 demo topics — a 6-step order
pipeline to trace across partitions, header-only correlations, a real time series to
window, plus duplicates and poison records for the audit to find.
With a private AI beside it, from published images
Process Mining can be answered by SpectraLLM
— a local RAG stack published under this same namespace — so the flowcharts and the anomaly
hunt run on your machine, with no API key and nothing leaving your network.
compose/spectra-hub.yml
wires the pair from published images only — no Maven, no npm, no SpectraLLM checkout, and
nothing built. It does need this repository, for the demo seeder and the three entrypoints it
mounts:
git clone --depth 1 https://github.com/devdownin/Kafkaexplorer.git
cd Kafkaexplorer
docker compose -f compose/spectra-hub.yml pull
docker compose -f compose/spectra-hub.yml up -d
Kafka Explorer on http://localhost:8080, the SpectraLLM UI on http://localhost:8088.
The first boot downloads ~4.8 GB of model weights in the background — nothing waits for it,
so both interfaces are up in seconds and Process Mining starts answering once the weights
land. Plan for ~16 GB of RAM; a GPU turns minutes per analysis into seconds, through the
.gpu.yml overlay
next to it.
One overlay goes further than sharing a model:
.ingest.yml
has SpectraLLM index the topics themselves, so the corpus answers questions about what is
in your messages, with cited sources — and the Explorer's own audits can read it. Every
variable is documented in
.env.example,
and the compose file explains each choice it makes.
✨ What you get
- 🖱️ Click-to-query — click a JSON key or XML tag in a message preview and it lands in your
SELECT/WHERE, withJSON_VALUE/XPath generated for you. - 🧠 Zero-config schemas — topics are sampled, their structure inferred (JSON, XML, Avro via Schema Registry), and registered as Flink tables in one click.
- 📝 A real SQL editor — Monaco (the VS Code engine), auto-completion scoped to the tables your query actually cites, query history, earliest/latest read modes, windowing assistant.
- 🔎 Search that says what it scanned — text, regex, field path, JSONPath, XPath, record key or Kafka header, over the whole topic, with hits, records scanned, why the pass stopped, and a cursor to continue. A search here is never silently partial.
- 🕸️ Lineage & tracing — an interactive graph of topics → tables → live jobs, resolved by Flink's own parser; plus cross-topic message tracing by key, header, JSONPath or XPath, streaming its hops as it finds them and comparing two keys side by side.
- 🗺️ A data model you did not have to draw — read a set of topics as tables, with the relations between them deduced from key-column names. Kafka has no foreign keys, so every edge is graded, states its evidence, and opens as a ready
JOIN— one relation or a whole subgraph. - 🩺 One-click cluster audit — poison messages, duplicates, flow drop-offs and latency, graded by severity, computed across your whole cluster in the background and diffable against the previous run.
- 📉 Consumer lag that grades itself — who reads a topic and how far behind, with
stalled(nothing assigned),partial(never committed on some partitions) andaheadcalled out rather than folded into one number. - ⏱️ Backlog in time, not just in records — the same 4 000 messages are four seconds of traffic on one topic and four days on another. Ask any group how long its oldest unread message has been waiting, from the topic page or as a scheduled metric; a partition that could not be read says so instead of reporting zero.
- 💡 KPIs proposed from what your cluster was observed doing — the Metrics page derives them from your audit, your traces, your running Flink jobs and your Process Mining mapping. Every card names the measurement it rests on and where its thresholds come from; nothing is created until you preview and save it.
- 🤖 AI process mining — reconstruct business flows as flowcharts and hunt anomalies with OpenRouter (the default: one key, most hosted vendors), Claude, any local LLM (Ollama, vLLM, LM Studio…), or a fully private SpectraLLM. Point it at a local provider and nothing leaves your network; the default is hosted, and both pages that call a model say which of the two you are on — read off the address, not the provider's name.
- 💰 What the AI cost, and a cap if you want one — every analysis shows the tokens and the price the provider reported, per call and per run, never an estimate; nothing is shown where a provider prices nothing, rather than a misleading zero.
CLAUDE_SESSION_COST_LIMIT_USDstops a live session once it has spent that much, which is what bounds a tab left open overnight. - 🔭 Kafka 4 native — KRaft controller quorum, KIP-848 consumer groups, share groups (KIP-932) and feature versions, in the UI and on
/actuator/prometheus. - 🔌 An MCP server for your agent, off until you say so — the same analysis layer over the Model Context Protocol: SQL over vanilla Kafka, schema inference, key tracing, graded consumer lag. Not a tenth translation of the
AdminClient. Every answer carries acoverageenvelope naming what it did not read, because an empty list is the one shape a model reads as "it does not exist". Read-only by registration, scoped by topic prefix — the SQL included — rate-limited, redacted, and behind a bearer token over TLS; the app's MCP page is the console for what it exposed, what it withheld and what every agent did with it.
Full feature tour: docs/FEATURES.md
🖼️ A look around
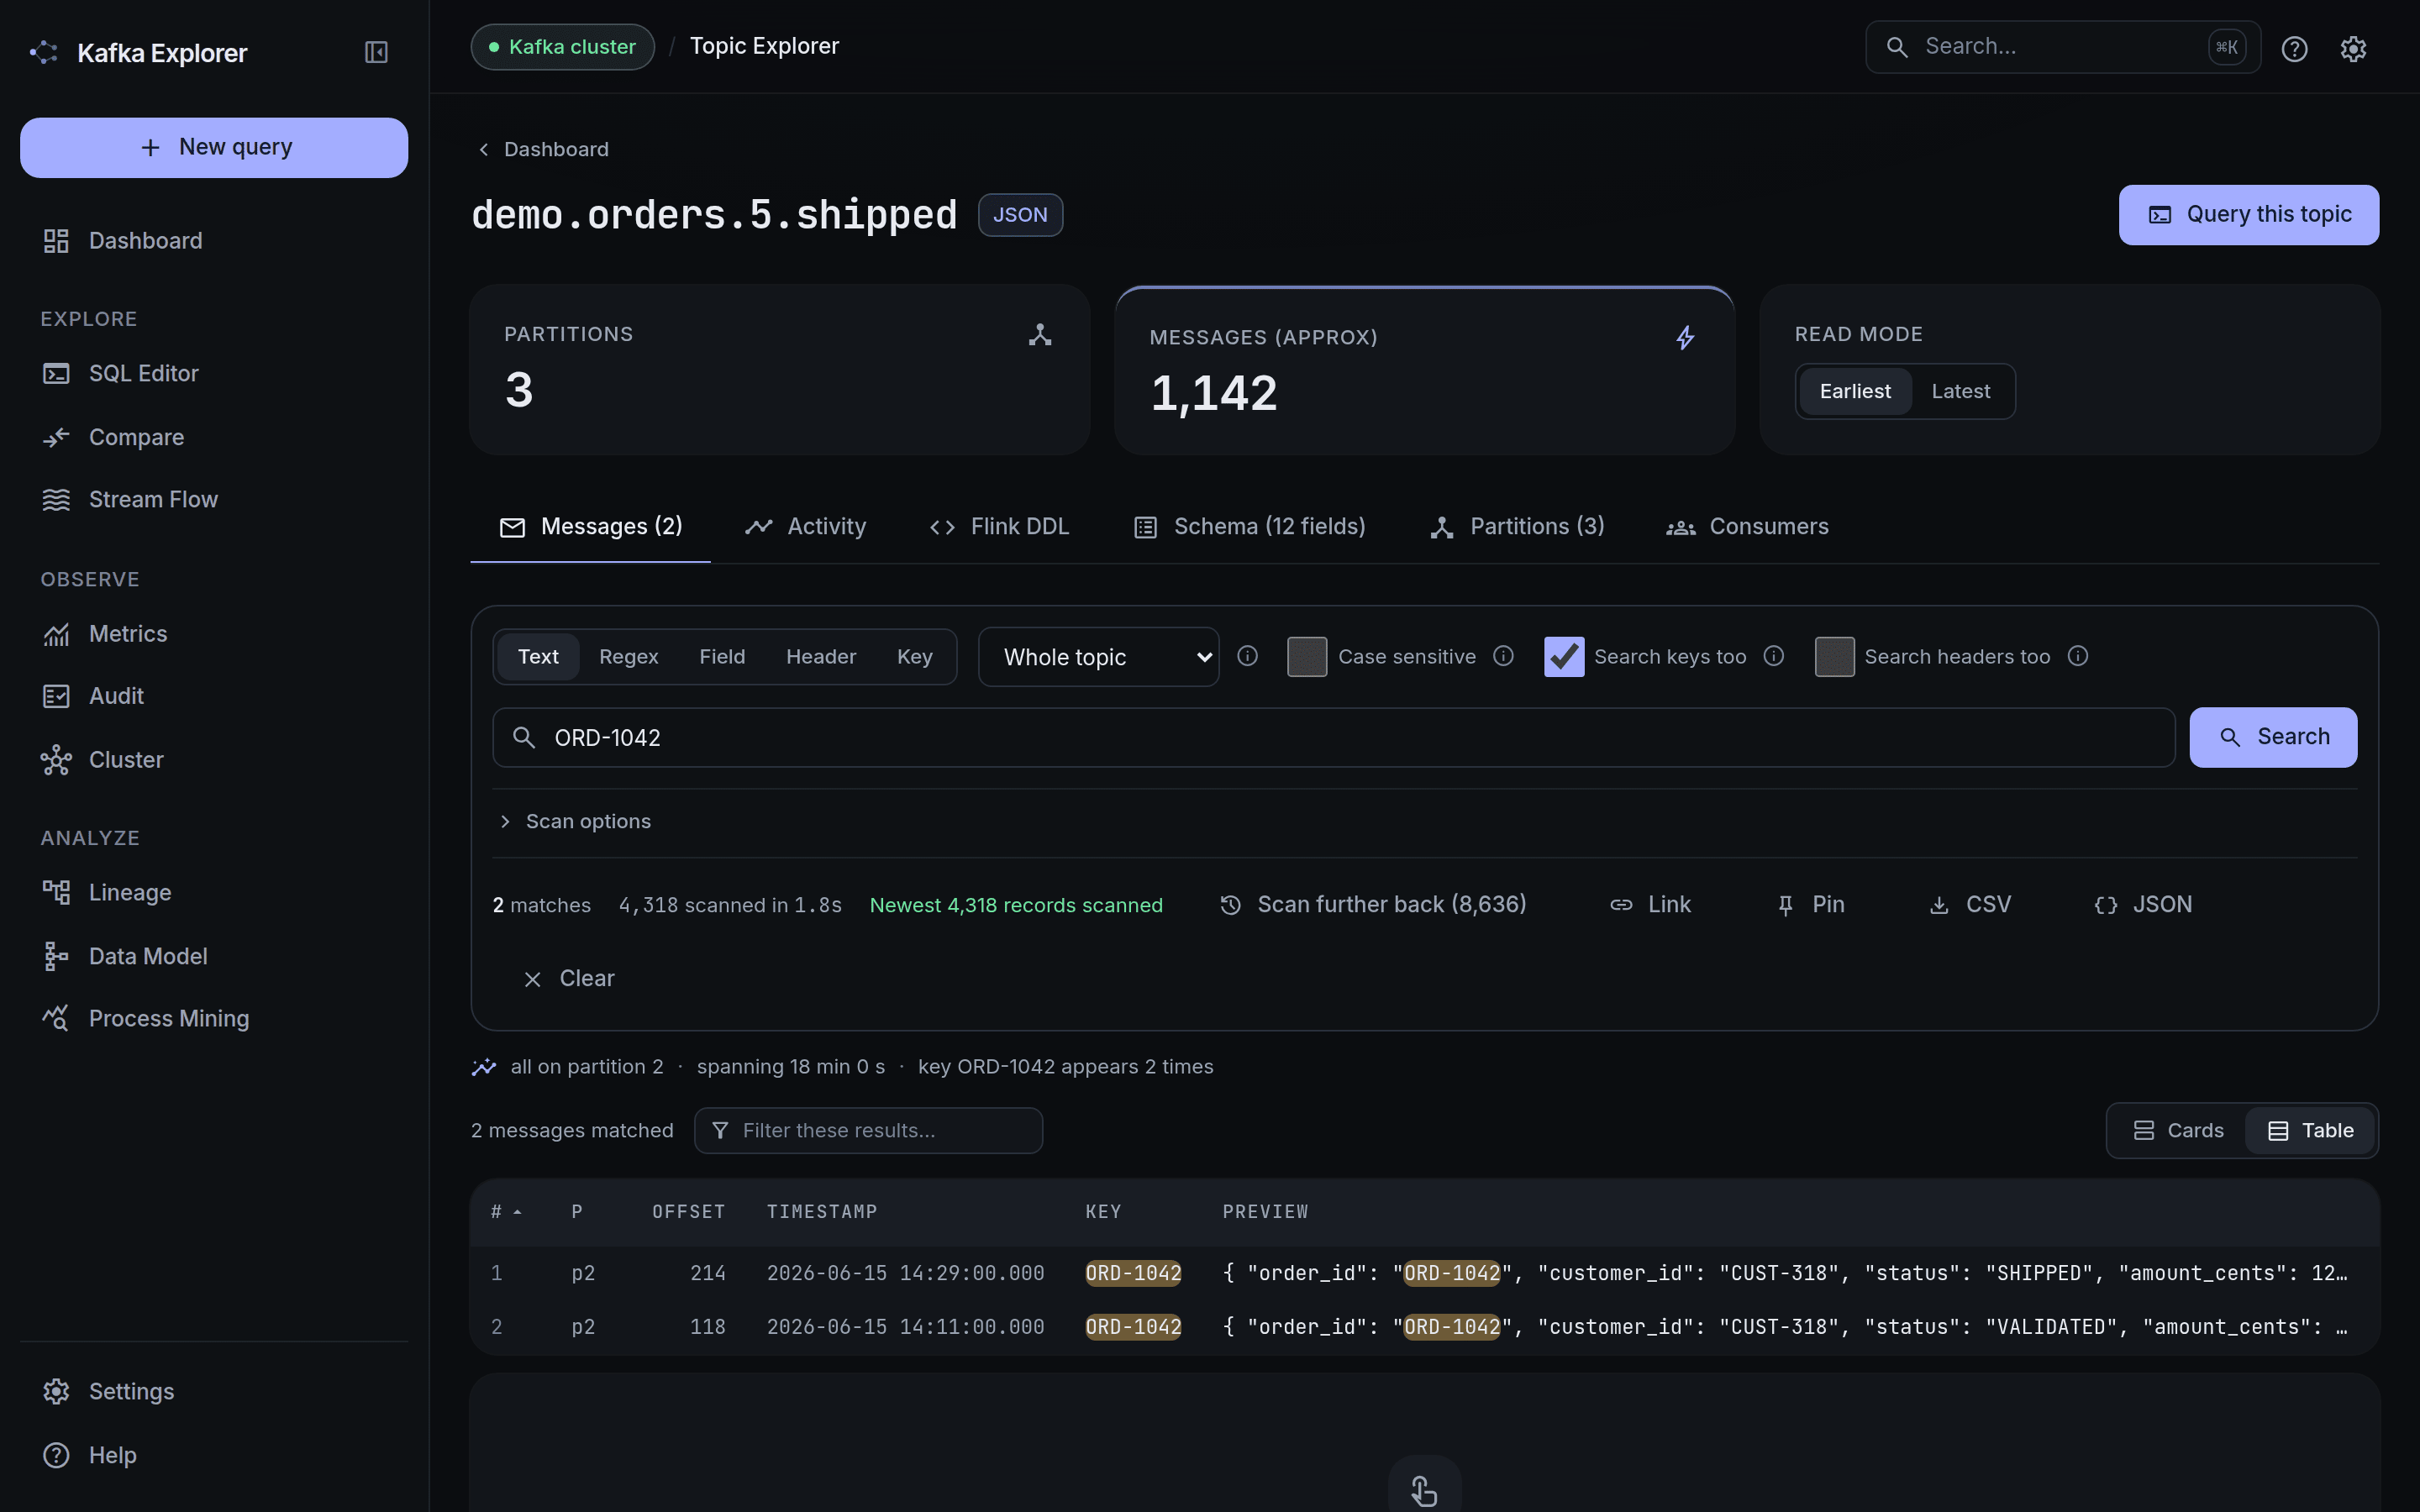
Topic Explorer — search the whole topic (text, regex, field path, JSONPath, XPath, record key or Kafka header), see the matches highlighted, and read exactly what was covered: how many records were scanned, why the pass stopped, and whether it can be continued.
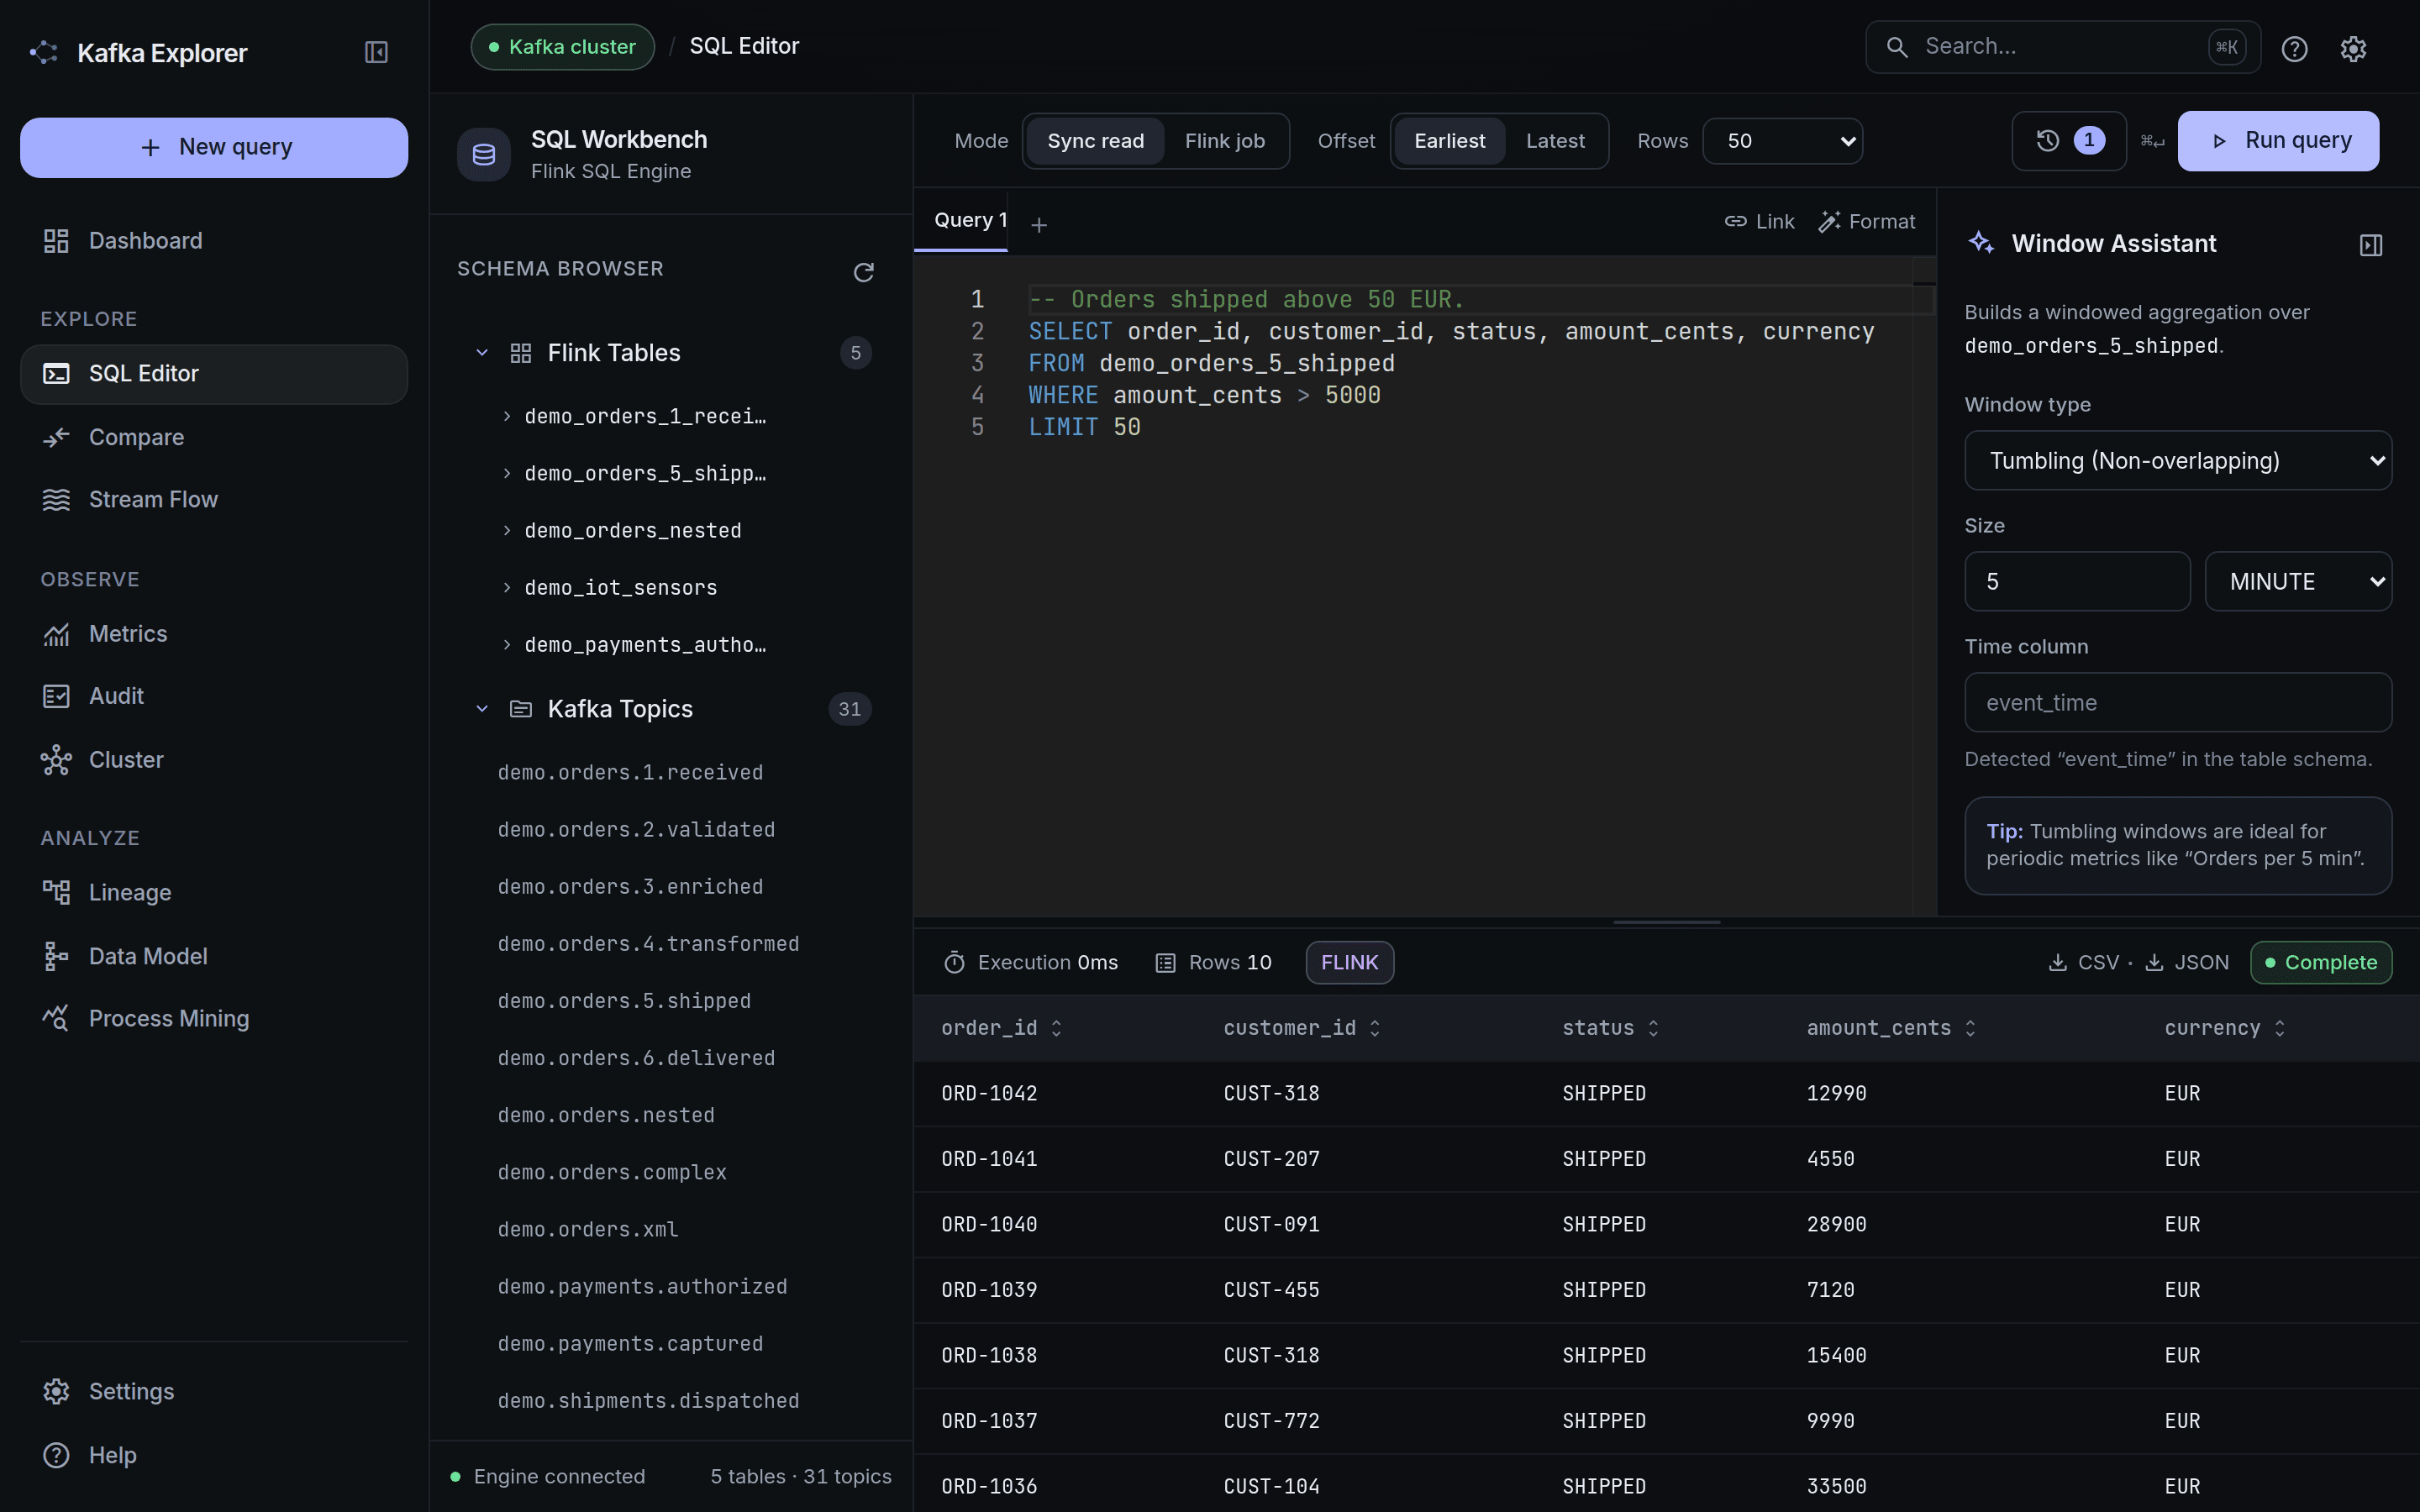
SQL Editor — Monaco, with the topics and Flink tables in the sidebar, completion scoped to
the tables the query actually cites, and the engine that answered stated on the result
(FLINK here, KAFKA_DIRECT when the planner falls back).
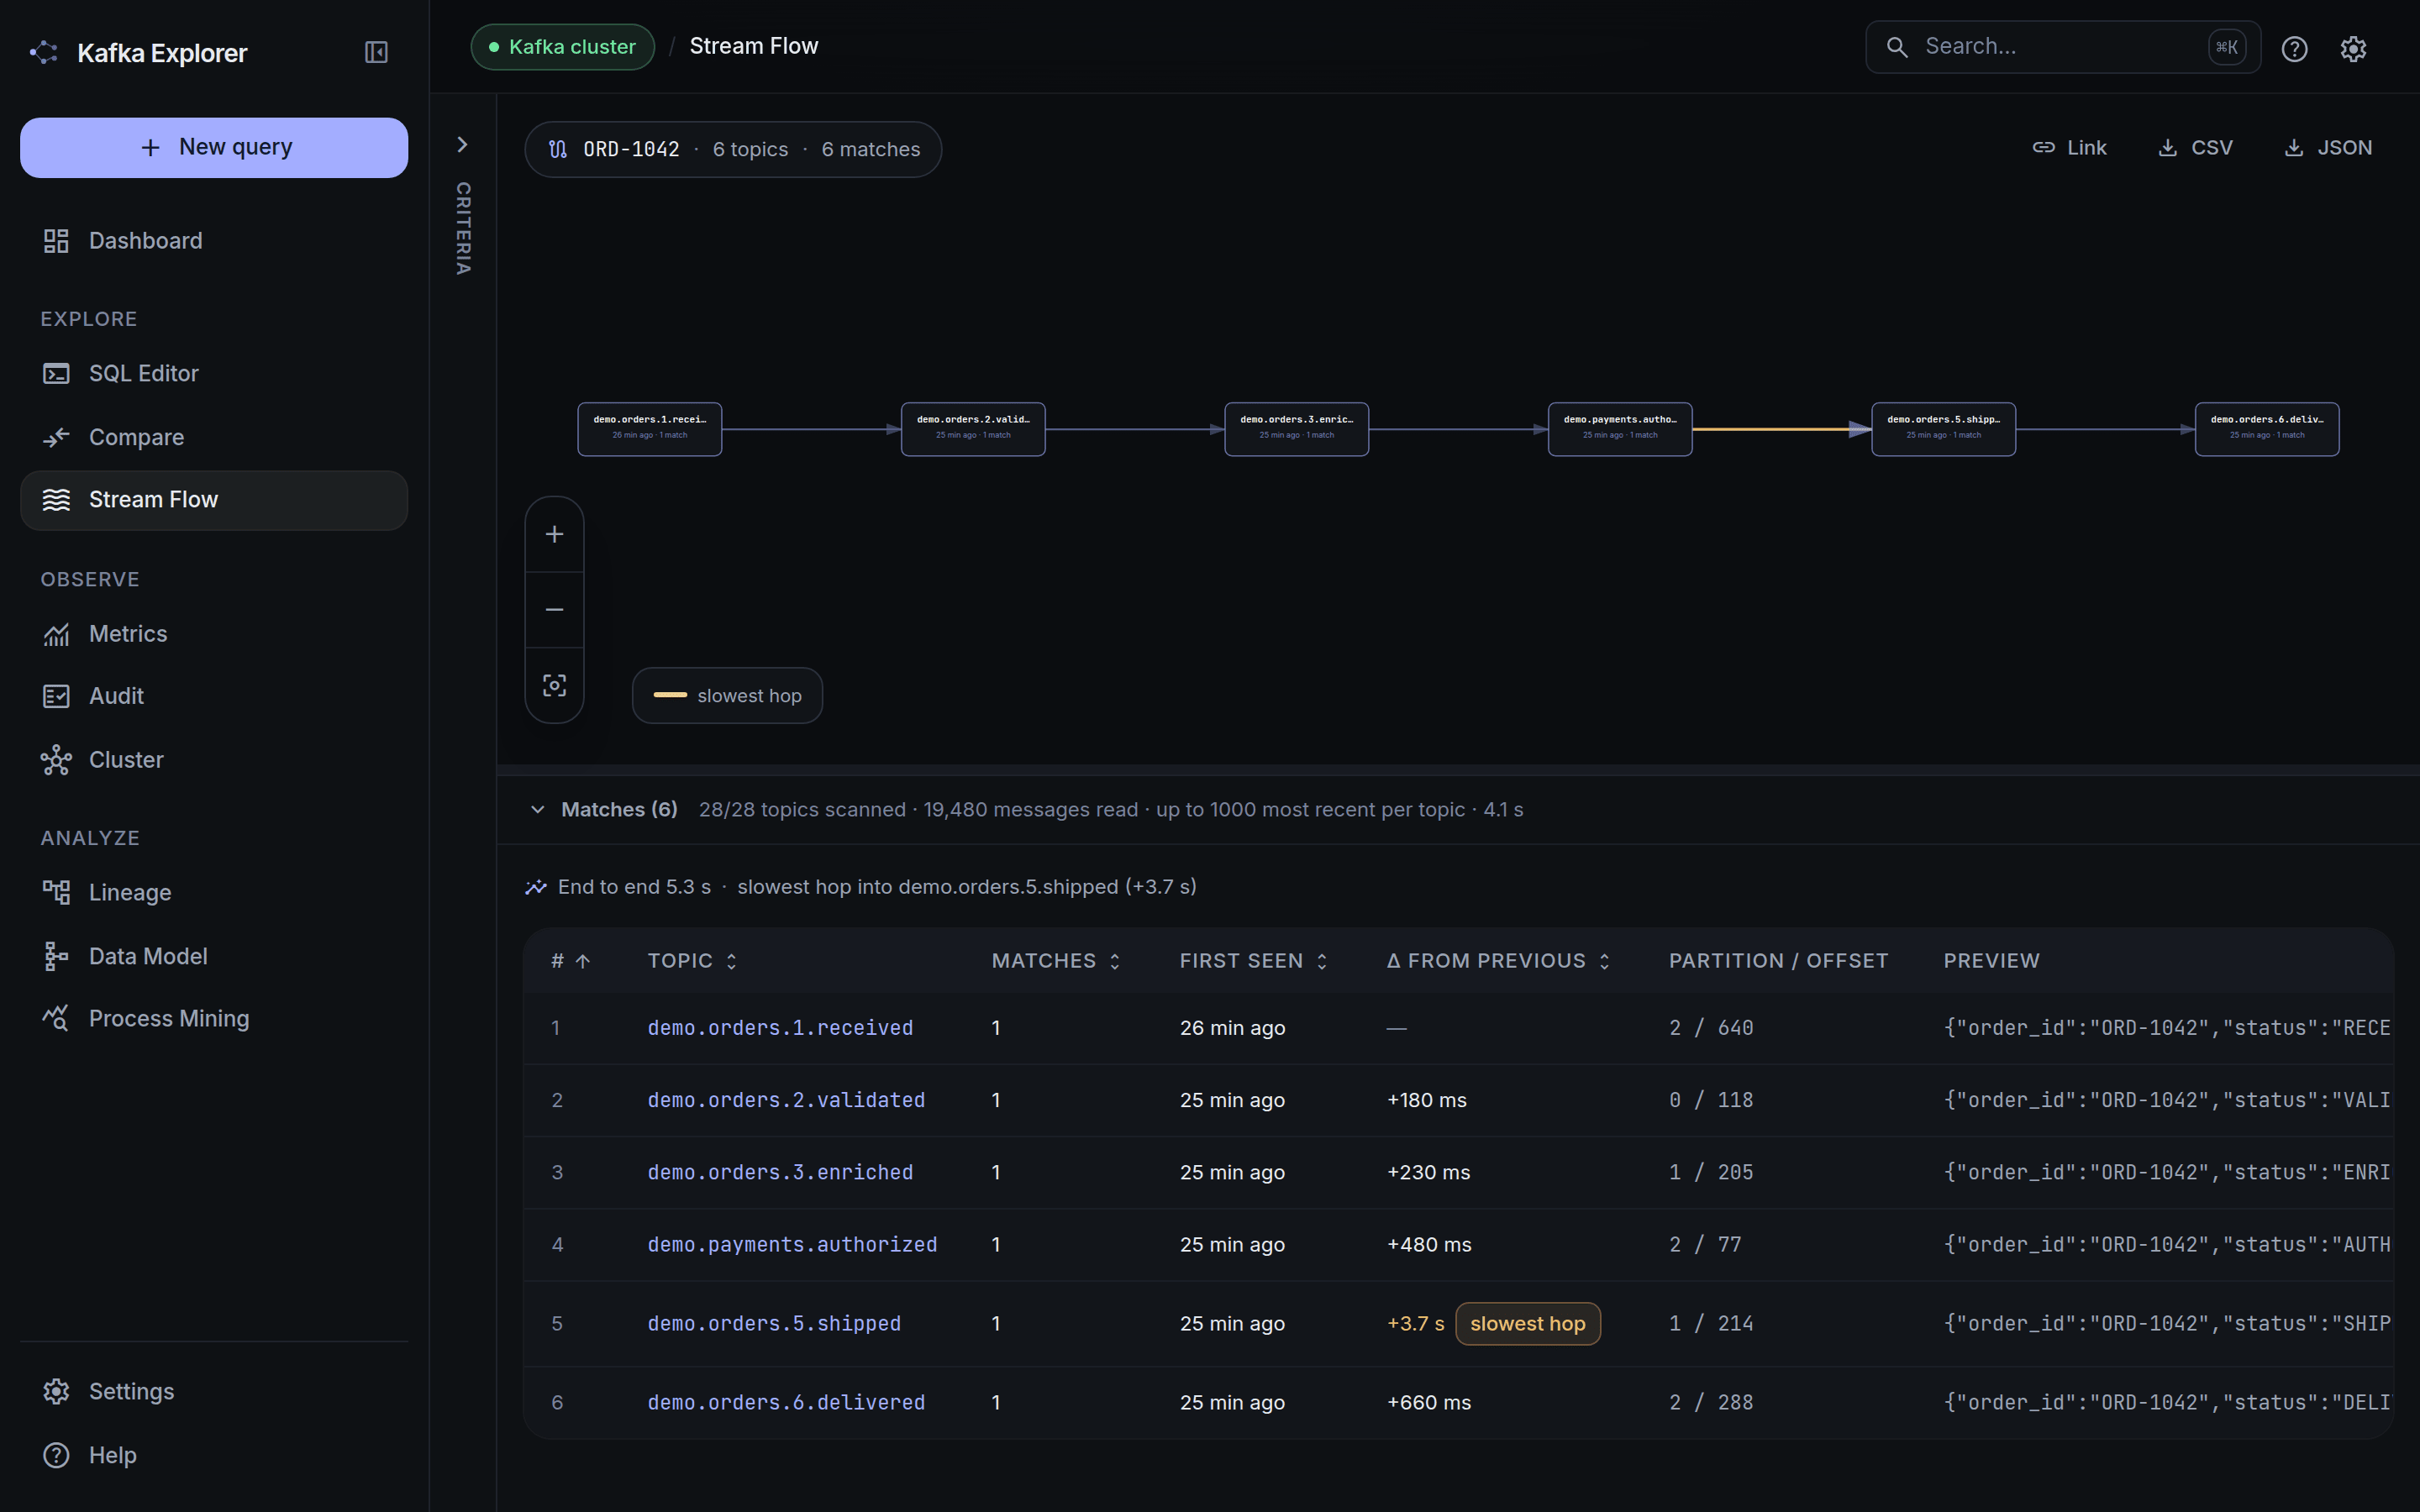
Stream Flow — follow one record key across the cluster. The chain is drawn from first sightings, each hop carries its latency from the previous one, the slowest is called out, and the evidence table underneath gives partition, offset and payload for every hop, so the graph can be checked rather than believed.
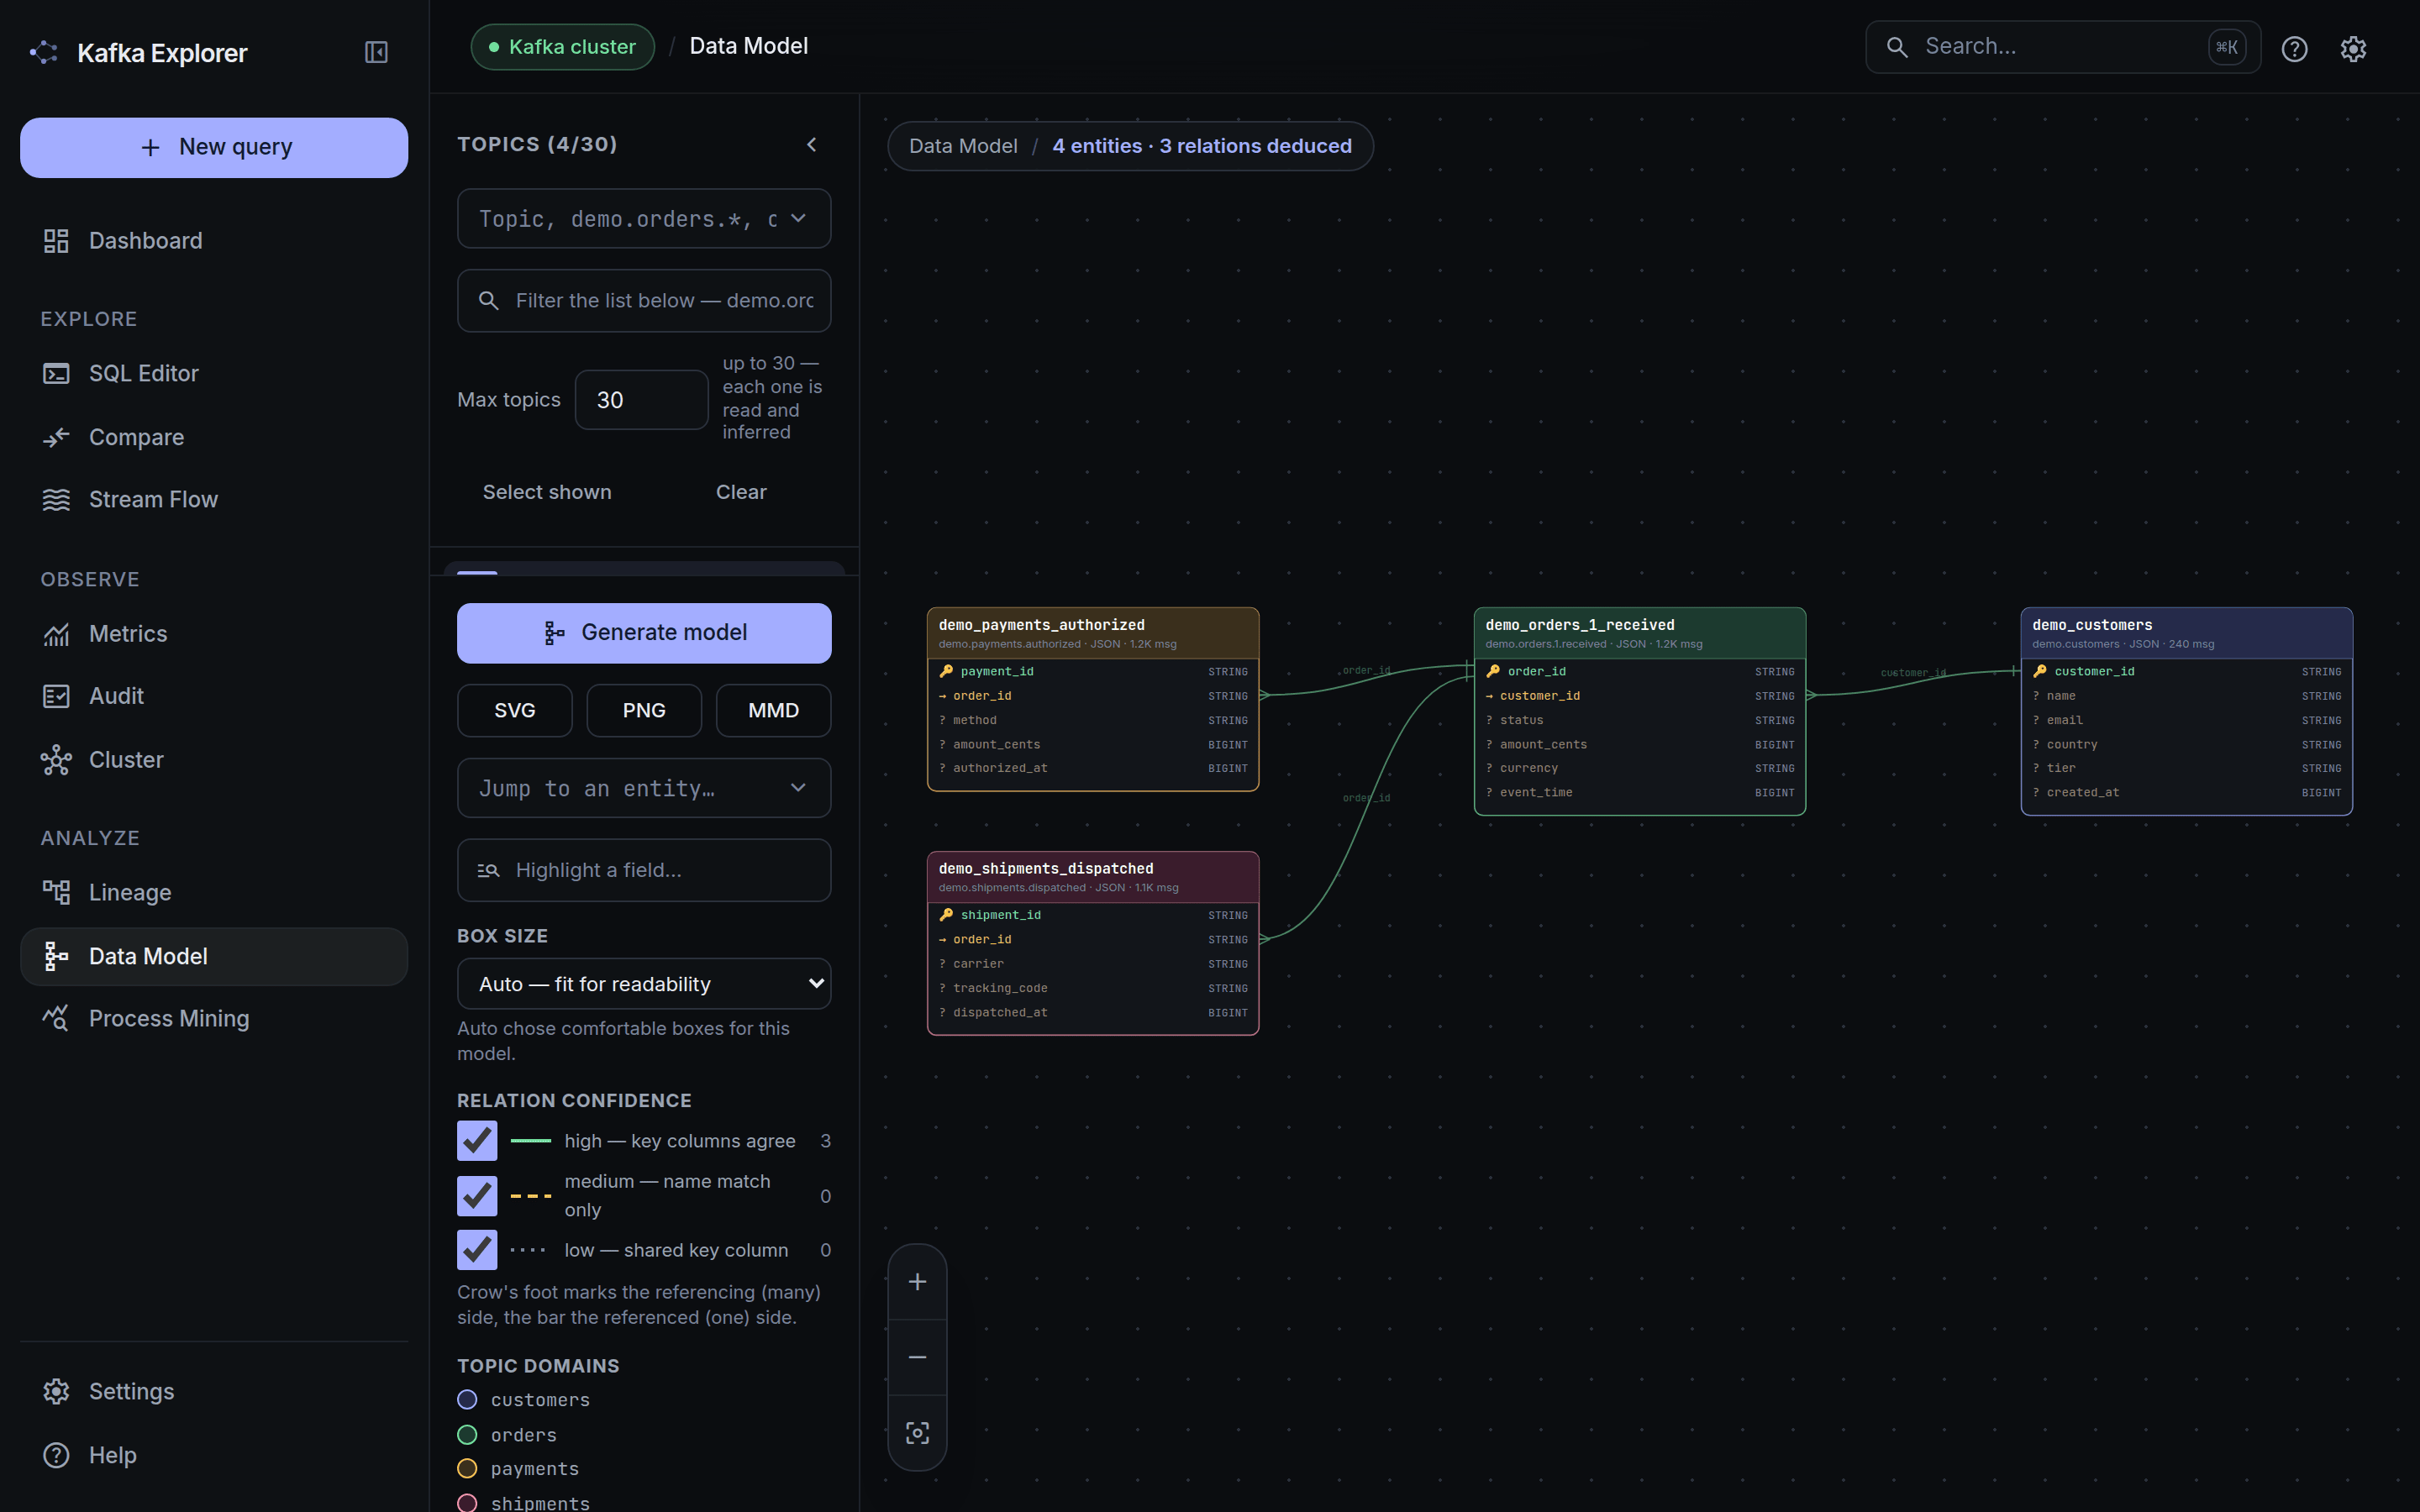
Data Model — pick a set of topics and read them as tables: each becomes a card carrying its
inferred columns, and the relations between them are deduced from key-column names. Kafka has no
foreign keys, so every edge is a claim rather than a fact — it is graded, drawn in a line style
that says which grade it is, and states in plain words the evidence it rests on. The key column is
detected, never invented: an entity with no id-like field simply has no key. A relation, or a whole
subgraph, opens as a ready JOIN in the SQL editor — and is refused rather than given an invented
predicate when the deduced relations do not connect it. Exports as SVG, PNG or a Mermaid
erDiagram, each carrying the coverage line and what is not drawn.
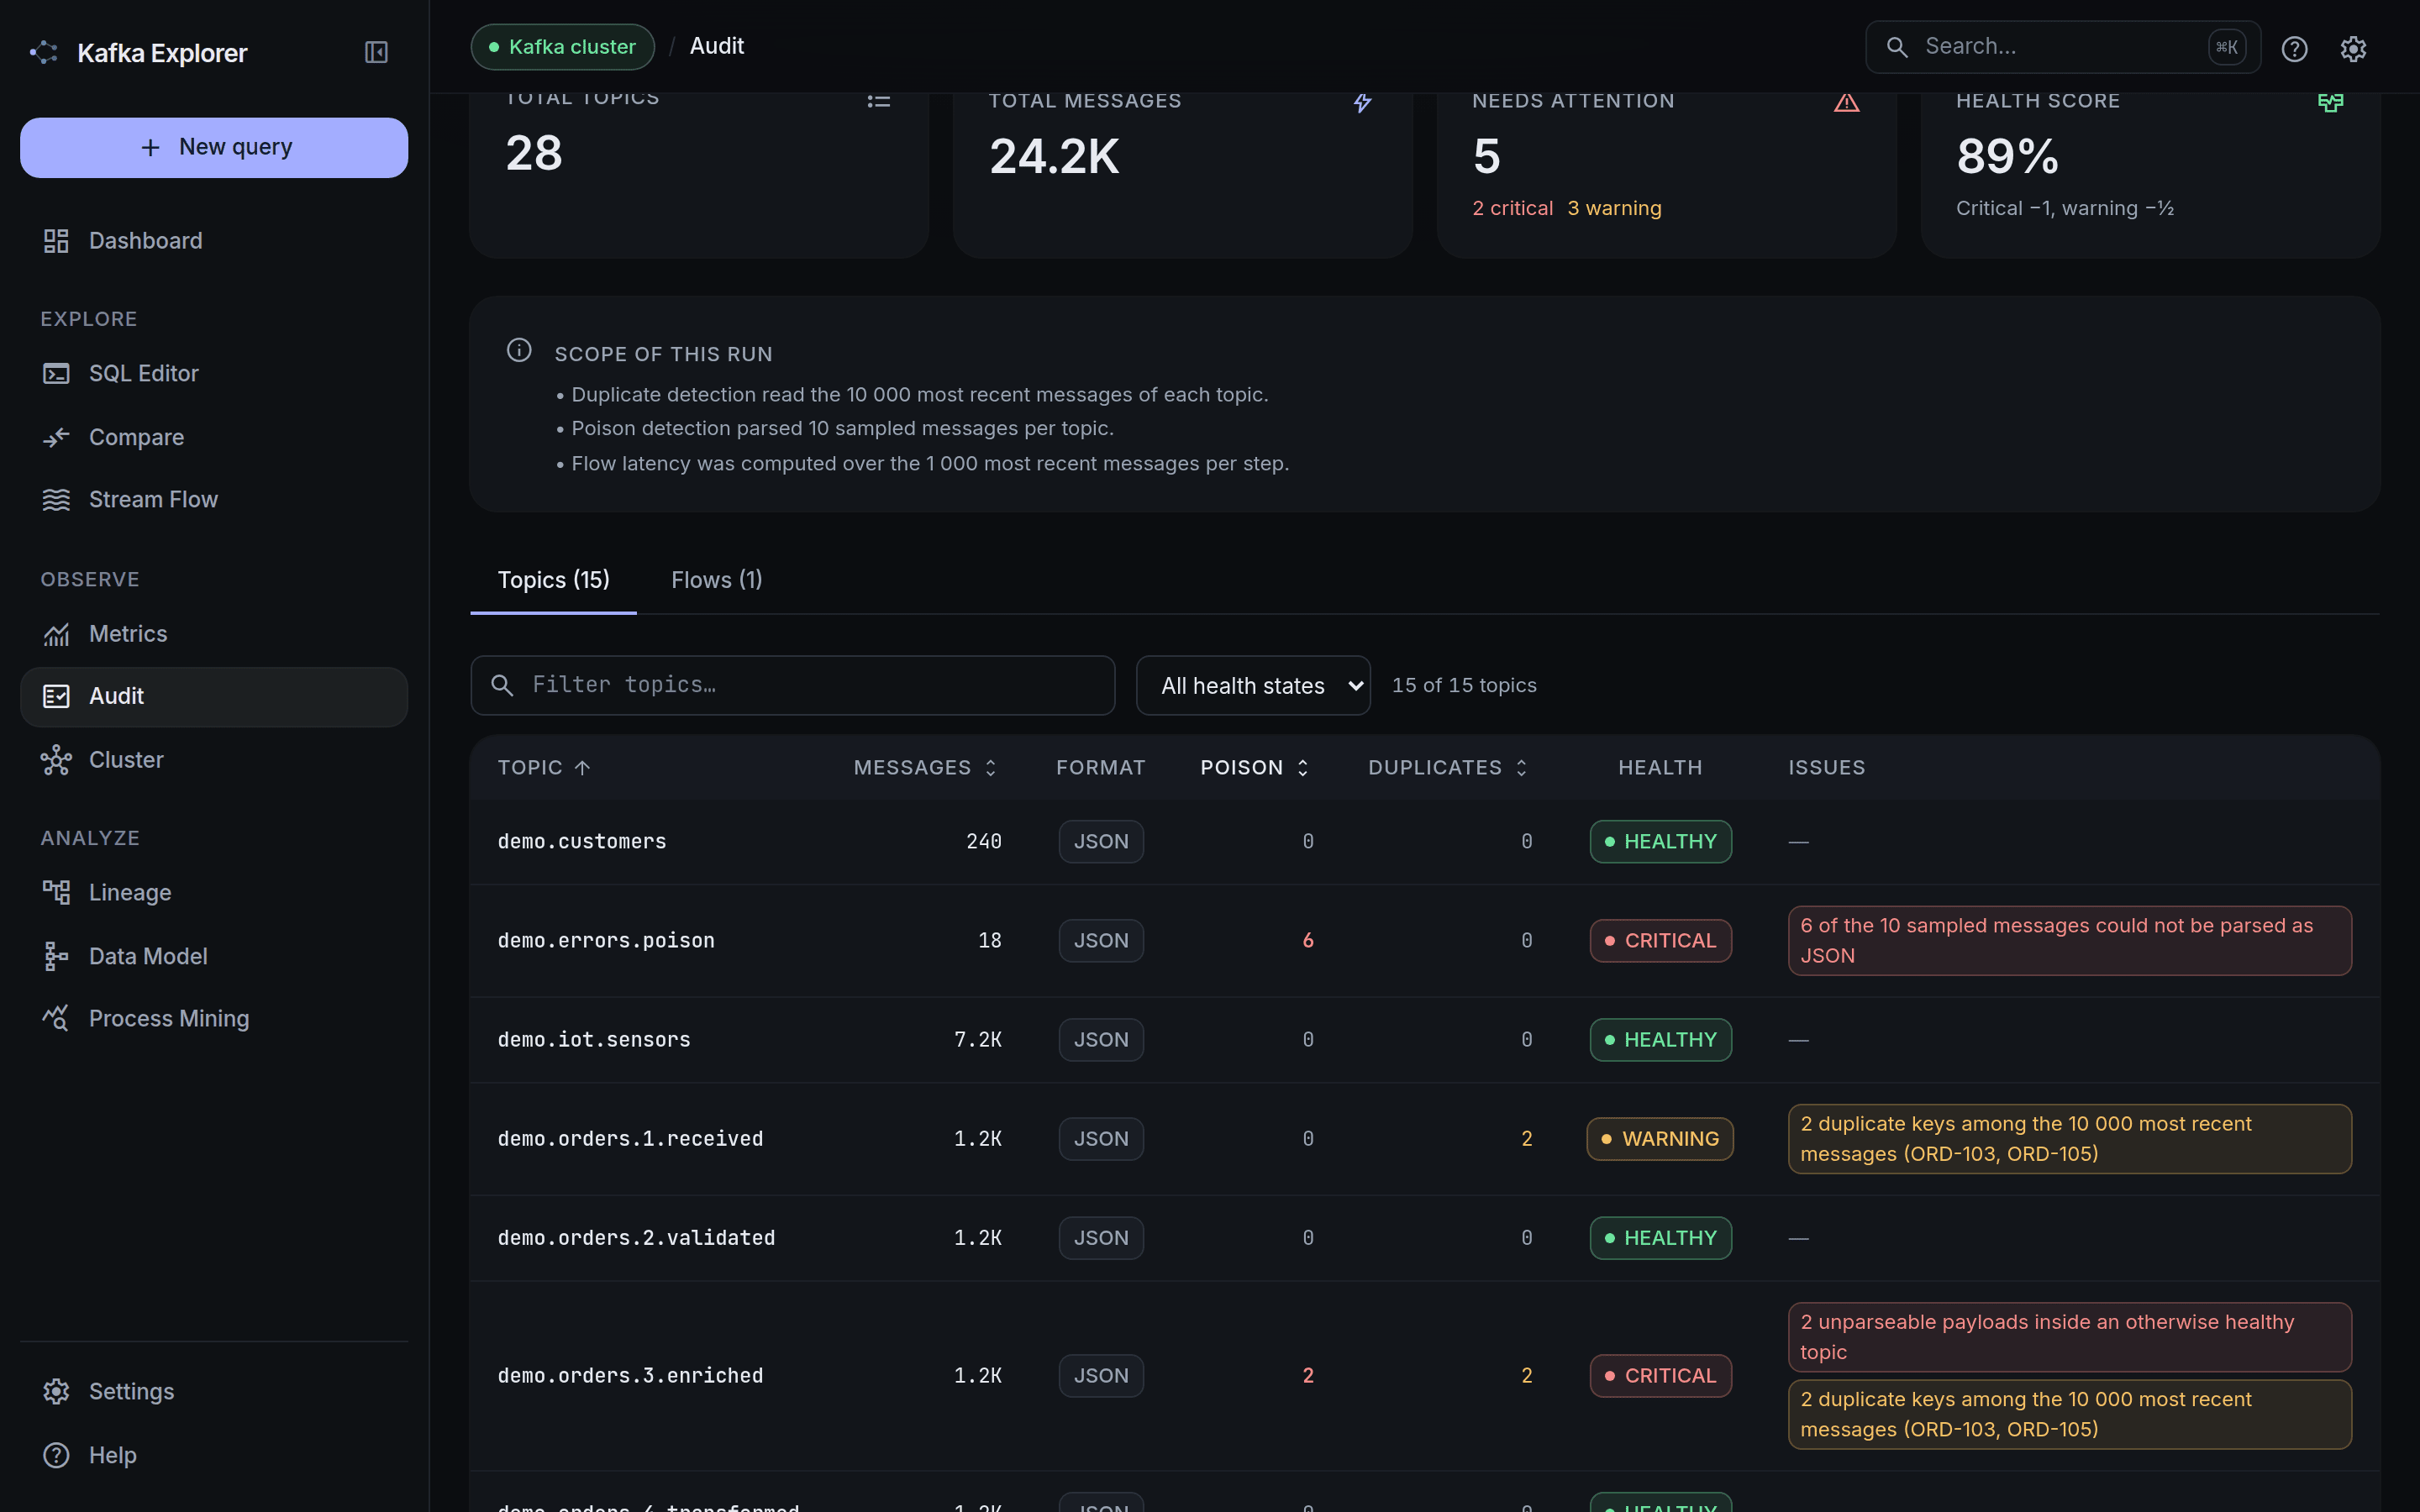
Cluster Audit — one click, whole cluster: message formats, poison payloads, duplicate
keys, flow drop-off and latency, graded HEALTHY / WARNING / CRITICAL. Every run states
its own scope, because a check that quietly sampled ten messages must not read like a verdict
on a million.
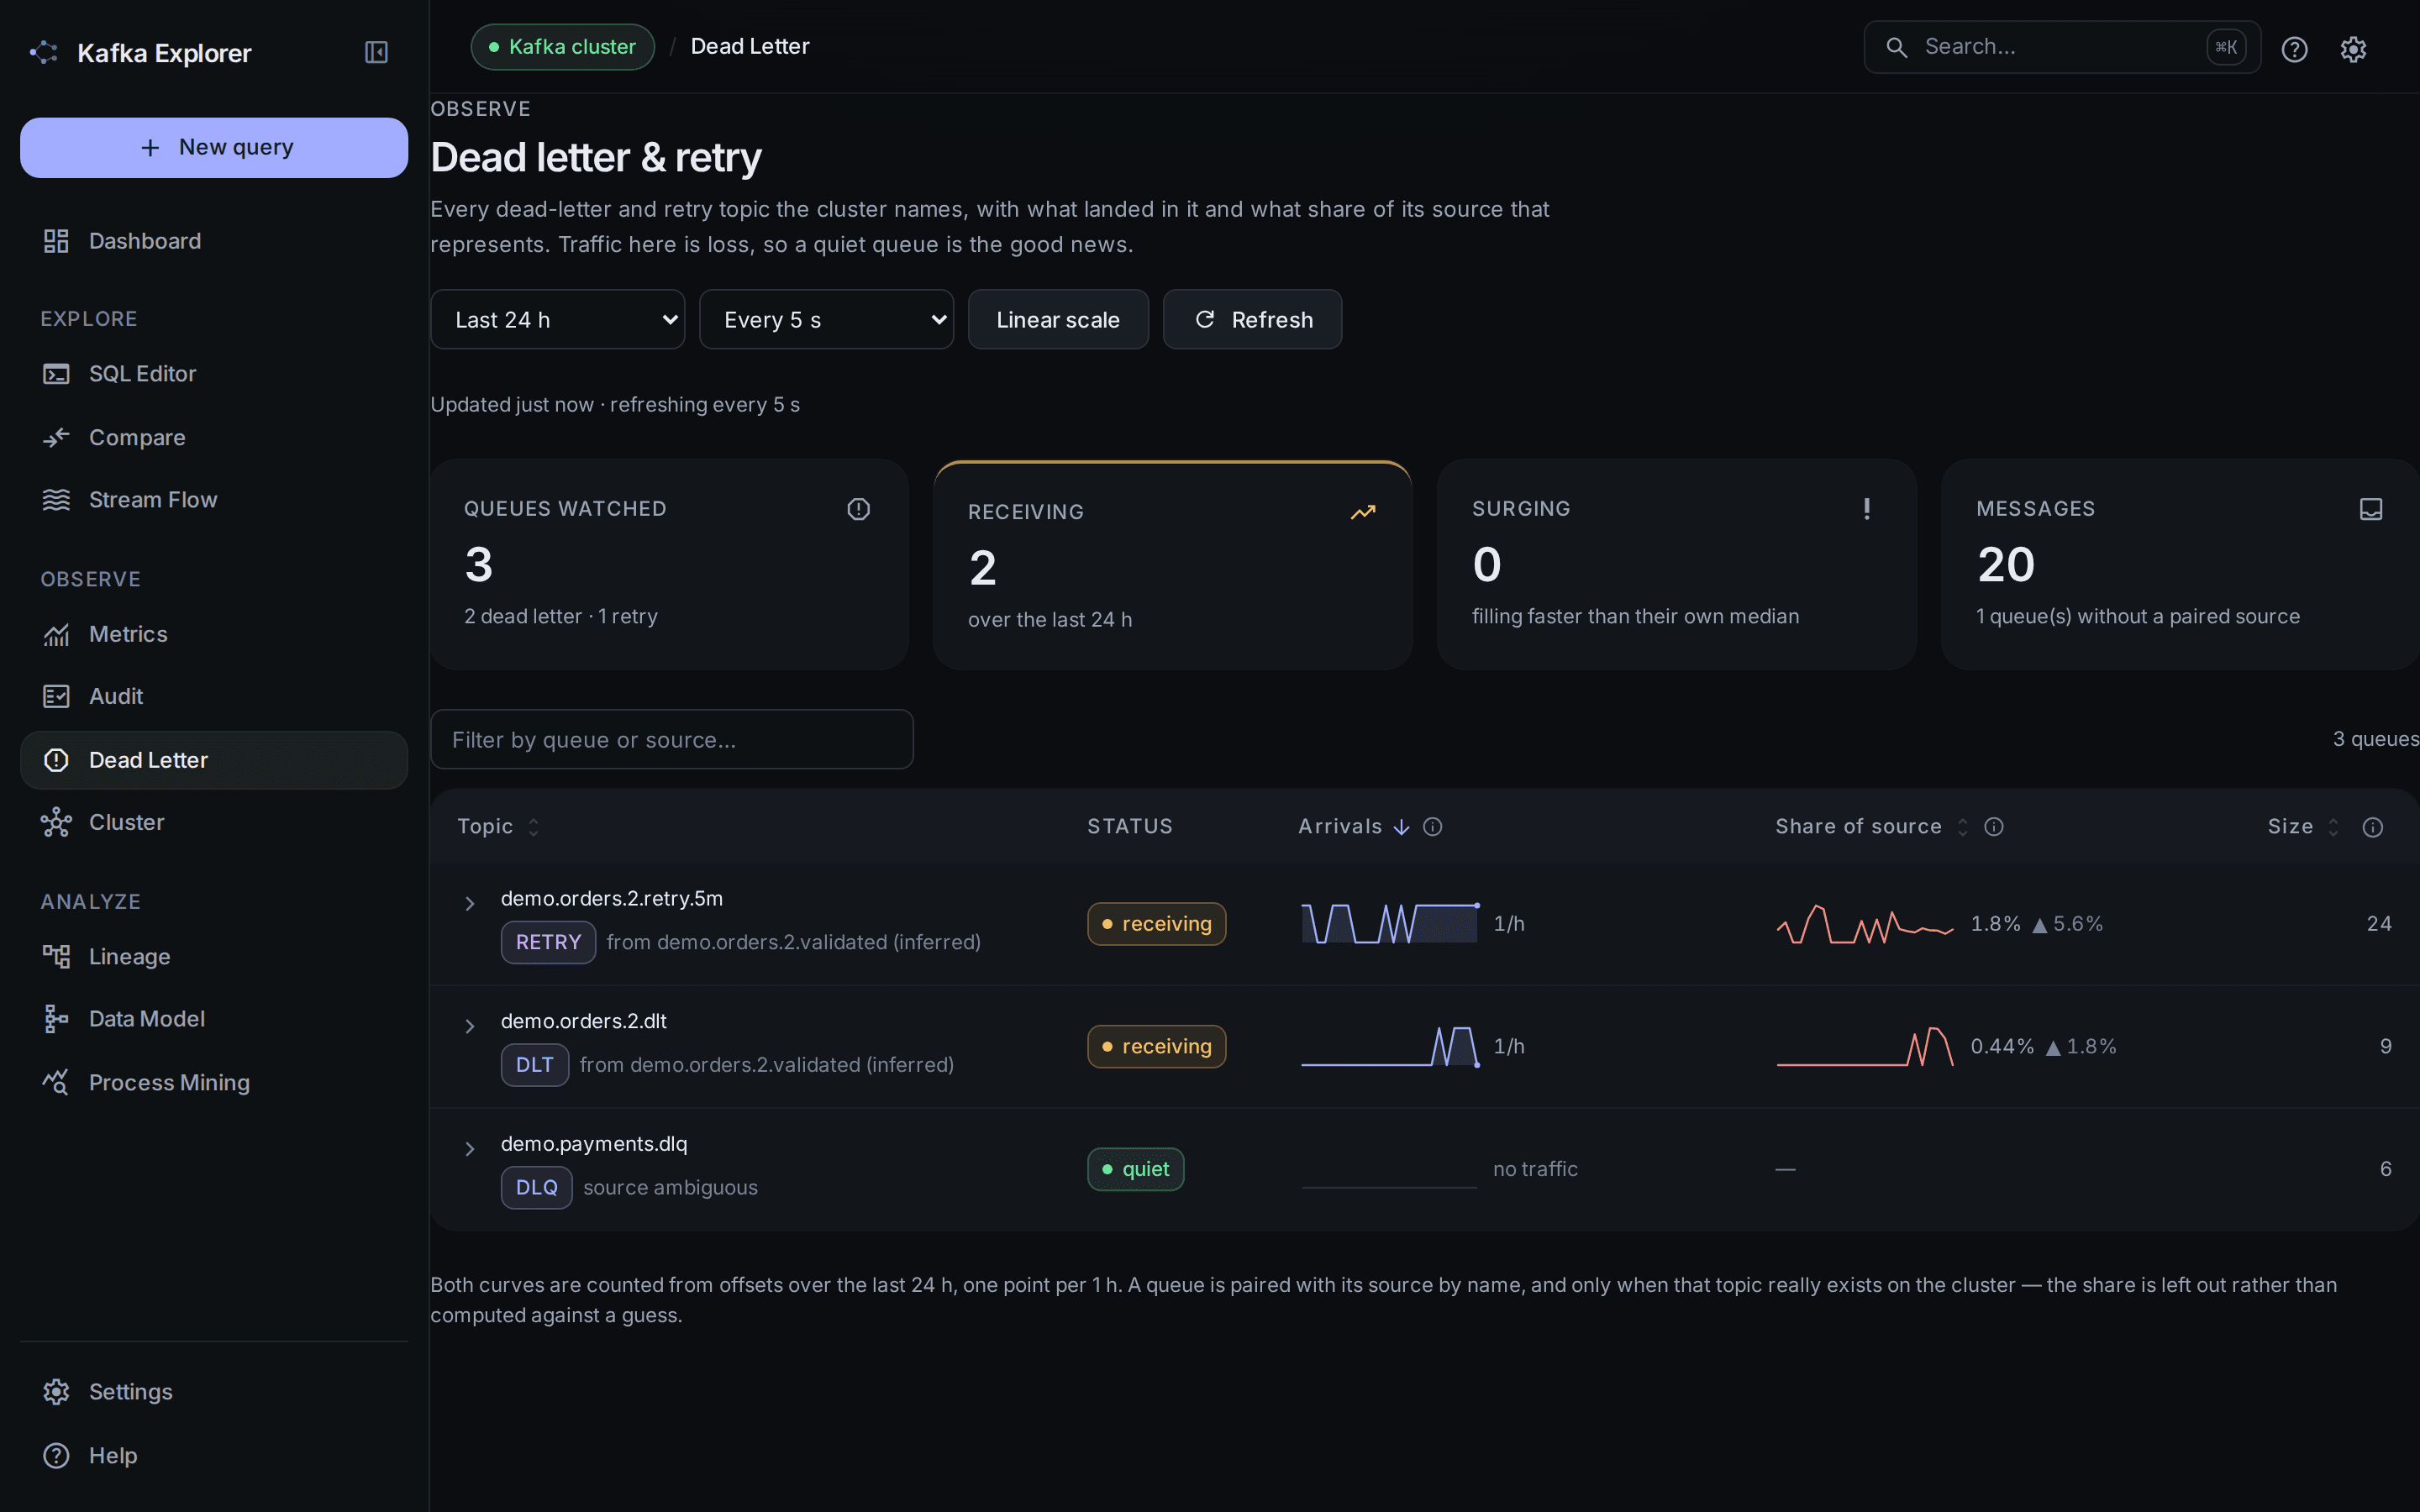
Dead Letter & Retry — every topic named .DLQ, .DLT or retry, with two curves each:
what landed in it, and what share of its source topic that represents. A count of failures
compares to nothing on its own; a rate compares between topics and between weeks. Where the
source cannot be identified without guessing, the page says so instead of computing a rate
against part of the traffic.
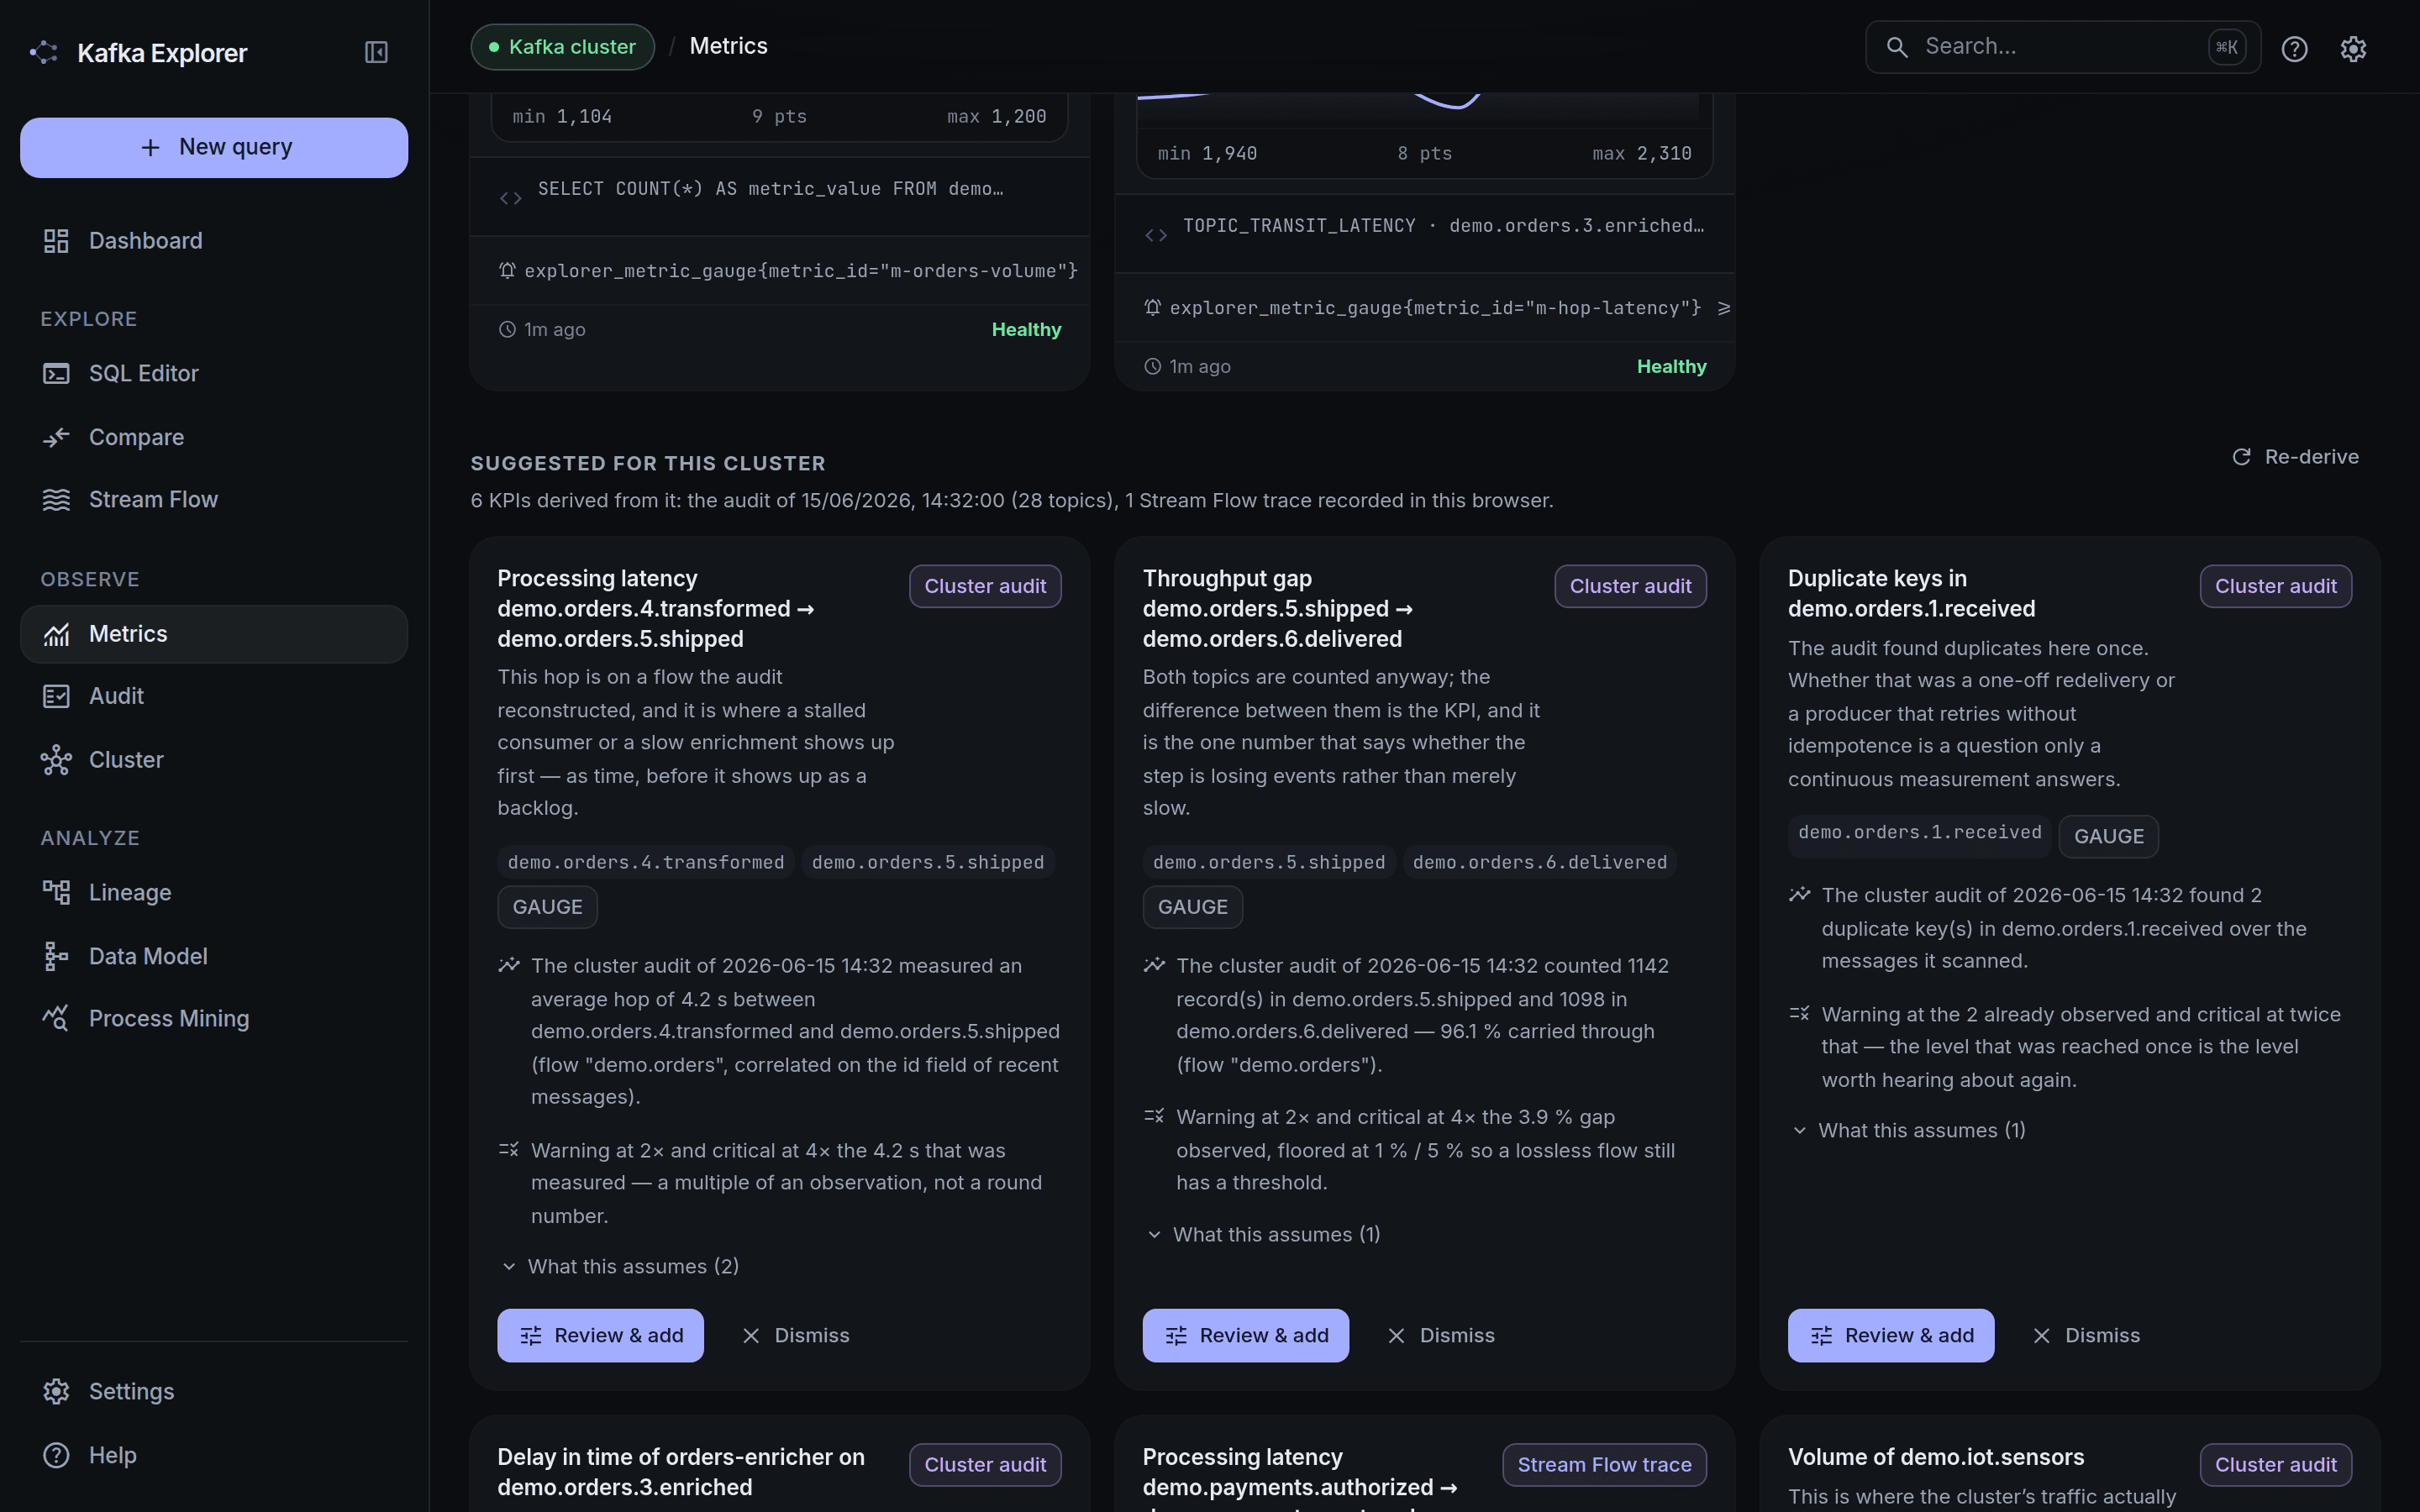
Metrics — turn a query into a Prometheus series, and let the page propose the KPIs your own cluster calls for. Each proposal carries the audit measurement behind it and states that its thresholds are a multiple of that measurement, not a round number someone liked.
Also there and not pictured here: Cluster (screenshot) with the KRaft controller quorum and client groups, Lineage, Compare and Process Mining.
🏷️ Tags
| Tag | What it is |
|---|---|
latest | The newest stable release. Pre-releases (v1.3.0-rc1…) never move it. |
1.2.3 | An exact version. Nothing here ever re-pushes one. |
1.2 | The latest patch of that minor line — it moves. |
Architectures: linux/amd64 and linux/arm64 (Apple Silicon, Graviton — natively,
not under emulation). CI builds and boots both before a version is cut.
In production, pin the digest, not the tag. "We never re-push 1.2.3" is a promise;
@sha256:… is a property. Every release
publishes its digest with the pull command:
docker pull compagnonsdudev/kafkaexplorer@sha256:<digest-from-the-release-notes>
The same image, same digest, is also published on GHCR:
docker pull ghcr.io/devdownin/kafkaexplorer:latest
Images carry a full SLSA provenance attestation and an SBOM
(docker buildx imagetools inspect --format '{{json .Provenance}}' …). If Docker Hub's
tag listing shows a third, unknown/unknown platform next to the two above, that is those
attestations — an extra manifest in the index, not a broken build.
⚙️ Configuration
Everything is a Spring property, so any setting in
application.yml
can be overridden by an environment variable: uppercase it and turn . and - into _
(explorer.search-max-scan → EXPLORER_SEARCH_MAX_SCAN). The ones that matter:
Kafka connection
| Variable | Default | Meaning |
|---|---|---|
KAFKA_BOOTSTRAP_SERVERS | localhost:9092 | Your brokers. Kafka 2.1+ on the classic protocol. |
KAFKA_MODE | PLAIN | PLAIN, SSL or CONFLUENT_CLOUD. |
KAFKA_SCHEMA_REGISTRY_URL | http://localhost:8081 | Confluent Schema Registry, for Avro topics. |
KAFKA_CONSUMER_GROUP_PROTOCOL | consumer | KIP-848 incremental rebalances for the live consumer — needs a Kafka 4.x broker. Set classic for older brokers. |
KAFKA_TRUSTSTORE_PATH / _PASSWORD | — | SSL mode. Mount the store into the container. |
KAFKA_KEYSTORE_PATH / _PASSWORD, KAFKA_KEY_PASSWORD | — | SSL mode, mutual TLS. |
KAFKA_CONFLUENT_KEY / KAFKA_CONFLUENT_SECRET | — | CONFLUENT_CLOUD mode. |
All of it is also settable live from the Settings page — which is precisely why the app must not be exposed to an untrusted network (see below).
What is entered there is kept across restarts, in /app/data/settings.json (mount that
volume, or it goes with the container). A variable set here still wins over what was saved:
that ordering is what stops a file written weeks ago from silently overriding the
KAFKA_BOOTSTRAP_SERVERS you just changed, and it is the way back out of a saved address
pointing at a cluster that no longer answers. The boot log names any setting that happened to.
Credentials are written to that file too, readable by the container's user alone — set
EXPLORER_SETTINGS_STORE_SECRETS=false to keep them out of it, and they will have to be
re-entered after each restart.
LLM (Process Mining — entirely optional)
| Variable | Default | Meaning |
|---|---|---|
CLAUDE_PROVIDER | OPENROUTER | ANTHROPIC, OPENAI_COMPATIBLE, OLLAMA, OPENROUTER or SPECTRA. The default is a hosted gateway: message digests leave the host. Use OLLAMA or SPECTRA to keep everything on your own network. |
CLAUDE_BASE_URL | https://openrouter.ai/api/v1 | Endpoint of the provider. Blank falls back to the provider's own default — http://localhost:11434/v1 for OLLAMA. |
CLAUDE_MODEL | openai/gpt-4o-mini | Model name at that endpoint. OPENROUTER names models vendor/model — anything on its model list, though you need not know a name: the Settings page lists the models that fit this deployment, cheapest first. |
OPENROUTER_API_KEY | — | The OpenRouter key (sk-or-v1-…), and with the default provider it is required: an anonymous request is a 401. |
ANTHROPIC_API_KEY | — | The same setting under its historical name, read when OPENROUTER_API_KEY is unset. Required for ANTHROPIC; ignored by a local Ollama. On a machine that exports several, CLAUDE_API_KEY outranks both and is the unambiguous form. |
CLAUDE_USE_RAG | false | SPECTRA provider only: also retrieve from SpectraLLM's ingested corpus instead of reasoning solely on the messages inlined in the prompt. |
CLAUDE_COLLECTION | — | SPECTRA + CLAUDE_USE_RAG only: which ChromaDB collection to retrieve from. Blank uses SpectraLLM's default. |
CLAUDE_OPENROUTER_DATA_COLLECTION | DENY | OPENROUTER only: DENY restricts routing to upstream providers that do not retain or train on what is sent. ALLOW widens the choice of models back — a model served only by data-collecting providers is otherwise unroutable, and the error says so. |
CLAUDE_OPENROUTER_REQUIRE_PARAMETERS | false | OPENROUTER only: route only to providers implementing every parameter sent, making structured output a routing guarantee. Off by default because a model whose providers lack it then becomes unroutable rather than degrading. |
CLAUDE_OPENROUTER_MAX_PRICE_USD_PER_MILLION | 0 | OPENROUTER only: the most this deployment will pay a provider, in USD per million tokens, refused at the routing layer rather than counted afterwards. 0 = no ceiling. Applies to both published prices; completion is the dearer in practice. |
CLAUDE_SESSION_COST_LIMIT_USD | 0 | Spend cap, in USD, for one live Process Mining session — it stops itself when reached. 0 disables it. A live session calls the model on every window for up to twelve hours, so this is what bounds a tab left open overnight. Applies only where the provider reports a cost. |
PROCESS_MINING_PROMPT_CHAR_BUDGET | 120000 | Characters of Kafka messages one analysis prompt may carry — about 30 000 tokens. Lower it, or widen the model's window, when you point this at a small local model. |
Leave it alone and every other feature works — Process Mining is the only page that calls a model.
The prompt has to fit the model's window, and on every provider but one nothing here can check that — the window belongs to the endpoint. OpenRouter is the exception: it publishes each model's context length, so Test LLM compares the two and says which way it came out. Read that as a floor rather than a calibration; the estimate is deliberately optimistic, so a budget it passes may still not fit while one it rejects certainly does not.
The shipped default is sized for the shipped provider: a hosted
OpenRouter model has room for 30 000 tokens. It is when you point this at a local model that
the budget stops fitting, and it does so in silence: Ollama gives a
model 4 096 tokens unless the machine has the VRAM for more, this image's request carries no
num_ctx (the OpenAI-compatible endpoint would not read one from the body), and the default
budget above is roughly 30 000 tokens. Ollama does not refuse the excess — it drops the oldest
messages until the prompt fits, and logs that at debug level. The analysis then reasons on a
fraction of what it was given, with nothing saying which fraction. Raise the window
(OLLAMA_CONTEXT_LENGTH on the Ollama server, -c on llama.cpp) or lower the budget so the
two agree; the bundled stacks
set both together.
Runtime
Give the container ~2 GB and a real limit (mem_limit: 2g, --memory=2g, or a
Kubernetes memory limit). The image embeds a Flink runtime, and the JVM sizes its heap
from the memory it can see: with no limit set that is the host's, so on a 32 GB machine
it believes it may take 24 GB. 2 GB is what the project's own
limits overlay
allocates; a cluster audit over thousands of topics is the workload that wants more.
| Variable | Default | Meaning |
|---|---|---|
JAVA_TOOL_OPTIONS | -XX:MaxRAMPercentage=75.0 | Replaced wholesale if you set it — re-state the percentage alongside whatever you add. |
EXPLORER_CLUSTER_NAME | Kafka cluster | Label for this environment in the header — Staging, Orders prod. A display name only; the bootstrap address the app is really using is shown beside it on hover. |
EXPLORER_DEFAULT_MAX_ROWS | 50 | Rows a query returns by default. |
EXPLORER_DEFAULT_QUERY_TIMEOUT_MS | 10000 | Per-query wall clock. |
EXPLORER_MAX_CONCURRENT_JOBS | 10 | Continuous Flink jobs (INSERT INTO in Job mode) held at once; 0 removes the cap. Each submission starts its own embedded Flink cluster inside the app's process — measured at about 80 threads and 6 MB of heap per job — so this bounds a gesture that is easy to repeat from the editor. A refused submission names the count and this variable; running jobs are stopped from the dashboard. |
EXPLORER_AUDIT_MAX_DURATION_MS | 1800000 | Budget for one full cluster audit; 0 disables it. |
EXPLORER_SEARCH_MAX_SCAN | 20000 | Records one topic-search pass may read. |
EXPLORER_ACTIVITY_MAX_TOPICS | 100 | Topics one activity read may measure — the sparkline column of the dashboard asks only for the rows it displays. |
EXPLORER_ACTIVITY_MAX_LOOKUPS | 20000 | Ceiling on partitions × bucket boundaries for that read, which is its real unit of work. No record is read: the series comes from offsets alone. Topics past the budget are named in the response rather than silently absent. |
EXPLORER_STREAM_FLOW_MAX_TOPICS | 250 | Topics a whole-cluster trace reads (the most recently active ones). |
EXPLORER_DATA_MODEL_MAX_TOPICS | 100 | Ceiling on the topics one data-model run may analyse. The page carries the per-run budget (30 by default) and reads this ceiling from the server, so raising it needs no rebuild — each topic costs a sample read plus schema inference. |
EXPLORER_INTERNAL_TOPIC_PREFIX | — | Prefix for the three topics the explorer writes to your cluster for its own state (internal.audit.history, internal.metrics.config, internal.field.mappings). Empty changes nothing. Set it when the explorer shares a cluster with other tenants, or when your naming convention reserves a namespace per application. It never renames a topic of your own pipelines. A value Kafka could not accept in a topic na |
Tag summary
Content type
Image
Digest
sha256:7f268105f…
Size
336.6 MB
Last updated
5 days ago
docker pull compagnonsdudev/kafkaexplorer